A Sharpe of 2.1 From Nothing: The Second Number Your Agent Doesn’t Log

September 2026

I gave a research agent four years of prices with no predictable structure in them — none, by construction — and it came back with a long/short book, an in-sample Sharpe of 2.1, and a paragraph explaining the economics of an effect that does not exist.

That is the measurement in this post. The more useful result is the second one: 88% of that number is accounted for by two integers — how many backtests the agent ran, and how many of the winners it blended into the book it reported. Only one of those is in the log everybody proposes to collect.

This closes a sequence. In August, having built an agentic research pipeline in May and measured a 2× lift in hypotheses tested per week, I priced a risk I had not thought to price: independent research runs against the same model produce books correlated at 0.62, a crowding exposure that appears in nobody’s risk report. That post ended with a claim I stated and did not measure — that faster hypothesis generation makes overfitting worse rather than better. This is the measurement, and my pre-registered prediction about how it would come out was wrong.


The one property agentic research has that human research never had

Every multiple-testing correction in finance founders on the same rock: you cannot observe the denominator. Harvey, Liu and Zhu built their t-statistic hurdle on an estimate of how many factors had been tried across the profession, not how many were published [1]. Harvey’s 2017 AFA presidential address is largely an argument about unreported trials [2]. The Deflated Sharpe Ratio requires you to supply the number of trials, and its authors are candid that in practice you are guessing [3]. Each method asks the researcher a question the researcher cannot honestly answer: how many things did you try before this one?

An agentic pipeline is different in exactly one respect. It has to ask the harness for every backtest it runs. The trial count is not a memory or an act of professional honesty. It is a log file.

So I built a minimal research agent, gave it one tool, recorded everything, and checked what the log is worth. The short answer is that it is worth less than I expected, for a reason that turns out to be measurable and fixable.


Setup

The harness. One command: submit up to 25 expressions, receive their in-sample scores. At most 12 such calls. The agent never sees prices, dates, tickers, or the holdout — the panel is anonymised to integer asset IDs and an integer time index, and the holdout files were physically absent from the filesystem while the runs executed. Every submission is logged with a timestamp, alongside a one-line hypothesis per batch and a free-text journal. The run ends when the agent reports exactly three signals.

What a “book” is, and the two counts that matter. Every arm’s output is scored the same way: three signals, equal-weighted into one book. The pre-registered primary rule takes the three highest-scoring signals a run evaluated, not the three it chose to report — the gap between the two is small and is itself reported below. N is the number of trials in the log. k is the number of additive legs in the resulting book: three for a searcher whose signals are single expressions, more for one whose signals are themselves sums. Those two integers carry the whole argument.

The signal language. A small price-only grammar: returns, moving averages, rolling moments, range position, rolling beta and correlation to the equal-weight panel, plus cross-sectional and time-series normalisations and arithmetic. It is the grammar from the August post, which matters — it was fixed before this hypothesis existed. Each signal becomes a dollar-neutral, rank-weighted long/short book with a one-day implementation lag.

The comparison arms. Three mechanical arms plus a no-selection placebo. The two that search run at the agent’s interaction schedule — 12 rounds of 25 candidates, feedback once per round. Matching rounds rather than evaluations is deliberate: in adaptive data analysis the damage scales with how many times you look and act, not with the raw query count [4].

ArmWhat it is
AGENTThe LLM researcher above
OPTEvolutionary search over the same grammar, at three selection pressures (soft, medium, hard — how aggressively each generation is bred from the current leaders)
CANON-SAMPLERCanon-shaped expressions with jittered parameters, no feedback — prior direction without optimisation
CANON placeboTwelve published anomalies in the same grammar, no selection at all

The data. The primary setting is synthetic: factor-structured panels with regime-switching volatility and fat tails, and zero predictability by construction. Volatility is forecastable; returns are not. The true Sharpe of every signal is zero, so every point of in-sample Sharpe is selection, and I can generate independent panels at will. The second setting is the real NASDAQ panel from the August post — 1,280 names, 2018–2023, train through 2021, holdout 2022 to May 2023.

The analysis plan, estimators, inclusion rule and predictions were committed to git before the first agent run. The repo holds the commit history, every harness log with its batch notes and research journals, a manifest of all 227 attempted runs including the five abandoned and why, and a list of every deviation from the plan.


1. What a research agent does with data that contains nothing

Twelve independent zero-alpha panels, one agent run each, identical prompt to the real-panel runs.

Every run found something. Every run wrote a confident rationale. From the report of a run on a panel whose returns are serially unpredictable by construction:

“All three combine the two independently validated engines: long-horizon cross-sectional mean reversion (ma 120-250, plateau confirmed across ret, ma, minr and maxr formulations at horizons 60-250) and a weekly return echo (returns from days t-8 to t-5 predict positively, with a coherent oscillating lag profile).”

There is no echo. There is no reversal. There is nothing.

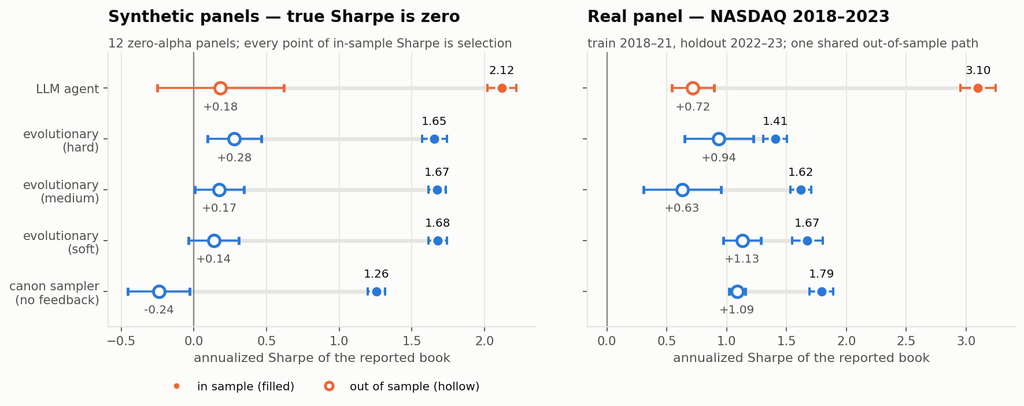
Zero-alpha panelsReported in-sample SharpeRealised out-of-sample Sharpe
LLM agent (12 runs)2.12 (SE 0.10)+0.18 (SE 0.44)
Evolutionary, soft (12 panels)1.68 (SE 0.07)+0.14 (SE 0.24)
Evolutionary, medium1.67 (SE 0.05)+0.17 (SE 0.22)
Evolutionary, hard1.65 (SE 0.11)+0.28 (SE 0.22)
Canon sampler, no feedback1.26 (SE 0.08)−0.24 (SE 0.29)

The reported book is the equal-weight composite of the three highest-scoring signals a run evaluated — the pre-registered primary rule, which is why it differs slightly from what the agent chose to report. True out-of-sample Sharpe is zero for every arm by construction, and every row is consistent with that. Standard errors are across panels.

A Sharpe ratio of 2.12, in-sample, on a book, over four years of daily data, from a panel with no signal in it.

A little over half of that is textbook. The expected maximum Sharpe of a single expression over the agent’s own median 146 logged trials is 1.15 (SE 0.03, across the twelve panels’ random-expression pools) — the expected-maximum-Sharpe effect [3], computed here as the exact order statistic over an empirical null pool drawn from the same grammar. That accounts for 54% of the 2.12. Note what the benchmark cannot do: those are single expressions, and it takes a single expression as the answer. Hold that thought — the missing 0.97 is the subject of section 3.

The agent’s own judgment is not the problem. It usually declines to report its top three by raw score, preferring what it calls “plateau” specifications; that restraint moves the number by 0.03 (2.08 chosen versus 2.12 argmax).
In-sample versus out-of-sample by search arm

2. It manufactures more than a machine built to overfit

Paired by panel, against the evolutionary optimiser at the identical interaction schedule, using only the twelve primary runs:

Contrast, in-sample Sharpe (12 paired panels)DifferenceSEt
Agent − evolutionary (soft)+0.440.11+3.9
Agent − evolutionary (medium)+0.450.11+4.1
Agent − evolutionary (hard)+0.460.09+5.2

On the real panel the gap is larger: 3.10 against 1.41–1.67.

That is the in-sample difference, and it is solid. The out-of-sample differences are not: those contrasts carry standard errors of 0.35 to 0.42, against a minimum detectable effect of about 1.0 Sharpe, and the pre-registered block bootstrap on the real panel returns a 95% interval of [−0.53, +1.99] for the agent’s realised Sharpe alone. Nothing in this study establishes that the agent’s books perform worse out of sample than a mechanical optimiser’s. What it establishes is that at a matched interaction budget, the agent converts noise into reported Sharpe more efficiently.

My pre-registered prediction was the opposite — that the model’s priors would act as a regulariser, keeping it in the published canon rather than in the noise, so it would overfit less. Wrong, at t ≈ 4.

3. Where the extra Sharpe comes from is not more searching

The mechanism is in the logs, and it is not model priors.

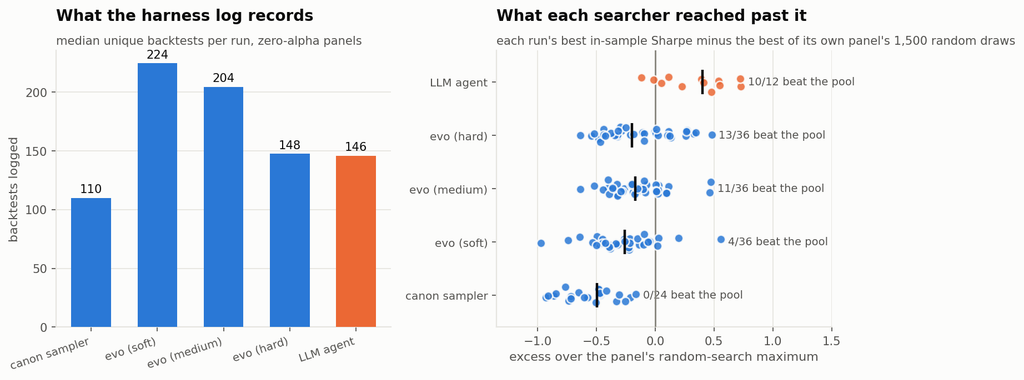
The agent logs a median of 146 unique backtests per zero-alpha run, against 148–225 for the evolutionary arms: level with the hardest setting, well below the softer ones. It is not searching harder — and note that the largest gap in the table above, +0.46, is against the arm that runs the same number of trials.

The difference is in what gets reported. Every run reports three signals, which are equal-weighted into one book. For the mechanical arms each of those three is a single expression, so the book has 3 legs. The agent’s three are themselves sums: a median of 4.2 legs each on zero-alpha panels, so its book carries about 12.5. That is the second integer, and no trial-count correction records it.

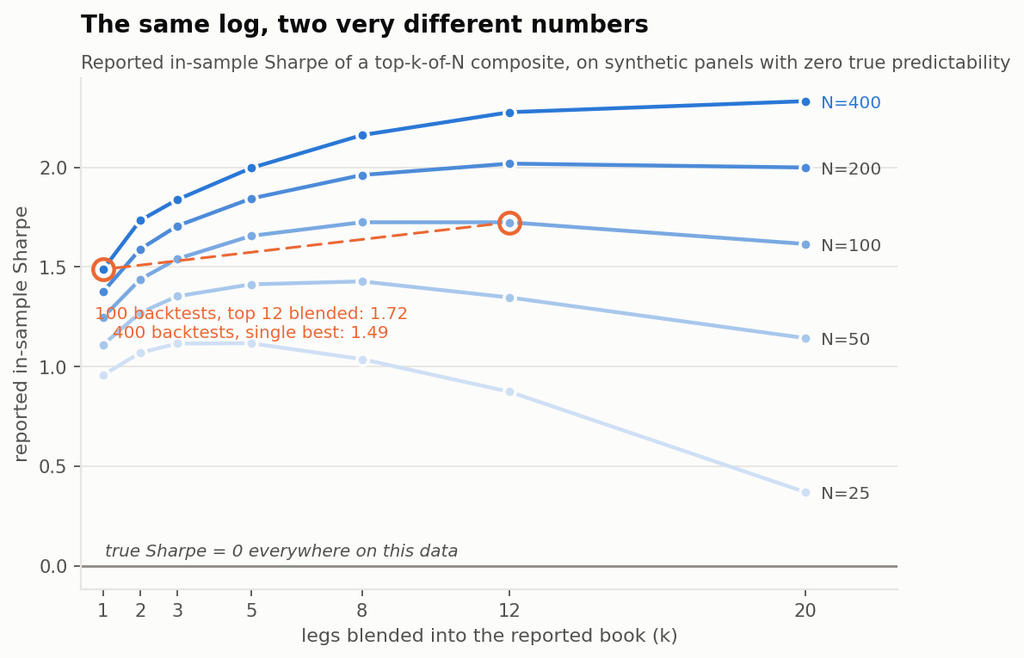
To isolate it I ran a controlled experiment on the zero-alpha panels with no agent involved: draw N random expressions, keep the top k by in-sample Sharpe, equal-weight them into a book, and record what the book reports.
The selection-plus-aggregation surface

Moving between curves is the familiar overfitting-versus-trials axis. Moving right along a curve is the aggregation axis nobody logs. The two trade off against each other: a pipeline that logs 100 backtests and blends its top 12 reports 1.72, while one that logs 400 and reports a single best reports 1.49. No alpha in either case, and the first pipeline’s log looks four times cleaner.

The arithmetic is standard portfolio algebra pointed at noise. Selecting k signals on in-sample performance and averaging them keeps the selected mean and cuts the variance — but the legs are not independent, so the gain is √(k / (1 + (k−1)ρ̄)), not √k. Fitting that form column by column over the monotone region gives ρ̄ of 0.41–0.47 at the trial counts that matter here, a ceiling of about 1.5× however many legs you add. That is why the curves flatten. They turn down at small N for a different reason: once k is a large fraction of N you are averaging in candidates that were barely selected at all. Novy-Marx made the combination point for strategies built from multiple signals and derived corrected critical values for it [5]; what is new here is an agent that was never asked to combine anything doing it unprompted, and the interchangeability of the two axes at a fixed log.

The closure. Take each run’s own logged trial count and its own book leg count, look up what blind top-k-of-N selection produces at that point on the surface, and compare:

ArmMedian trialsLegs in bookBlind top-k-of-N predictsActually reportedResidual
LLM agent14612.51.862.12+0.26
Evolutionary, hard14831.681.65−0.03
Evolutionary, medium20531.731.67−0.05
Evolutionary, soft22531.771.68−0.09
Canon sampler11031.561.26−0.31

Two integers and no model price the evolutionary arms to within 0.09, and account for 88% of the agent’s number. The residual is +0.26 (t ≈ 2.1 once the surface’s own estimation error is propagated) — small next to the 1.86 that blind selection explains. And the leg axis alone carries most of the agent’s edge over the mechanical searchers: holding trials at the agent’s own 146 and moving the book from 3 legs to 12.5 adds +0.25, against a measured agent-minus-mechanical gap of +0.45.

So the agent beats the optimiser and is beaten by blind selection at its own operating point, and both facts have one cause. It blends; they do not.

That also settles what happened to the estimator I pre-registered. I had planned to report an effective trial count — the random draws from this grammar needed to match a run’s best score. It cannot be computed for most agent runs: 10 of 12 exceed the best their own panel’s 1,500-draw random pool reached, so no trial count reproduces them. That is partly a property of a finite pool and it is not agent-specific — 13 of 36 hard evolutionary runs also clear their pool — so nothing here rests on it. The direction is informative, though: a deeper random-expression pool (depth 6, mean complexity 5.9 against the shallow pool’s 3.6) lifts the 99th percentile from 0.95 to 1.24 and the maximum to 1.79 without closing the gap, because random expressions almost never build composites — mean legs 1.15.

Depth is not the axis. Blending is.
What the log records versus what random search reaches

4. The real panel

Six agent runs on the NASDAQ panel, trained through 2021, scored on 2022 to May 2023.

Real panelTrainHoldoutLegs in bookDaily turnover
LLM agent (6)3.10 (SE 0.15)+0.72 (SE 0.18)6.00.24
Canon sampler (5)1.79 (SE 0.10)+1.09 (SE 0.07)30.45
Evolutionary, soft (5)1.67 (SE 0.13)+1.13 (SE 0.16)30.43
Evolutionary, medium (5)1.62 (SE 0.09)+0.63 (SE 0.32)30.26
Evolutionary, hard (5)1.41 (SE 0.10)+0.94 (SE 0.29)30.49
12 published anomalies, no selection−0.11+0.810.14

The last row is the control that makes the rest interpretable, and it is scored exactly like every other row — one equal-weight composite, same backtester, same holdout — with no selection applied. It does not decay across this boundary. It improves, from −0.11 to +0.81. The 2022–23 environment was kinder to these exposures on this universe than the training window was.

So the regime component of the agent’s decay is not merely small; it is negative. The control licenses one claim and not a stronger one: the unselected canon did not decay here, so the regime cannot explain the agent’s 2.4-point gap. It does not follow that selection explains all of it — the canon composite is loaded the opposite way from a book selected to score 3.10 in the training window, and the pre-registered random-search leg that would have measured the selection component directly was not run.

Note what the ordering does not do. It is not monotone — the medium evolutionary arm has the lowest holdout Sharpe of any arm, below the agent’s — and every one of those holdout differences sits inside the block-bootstrap intervals. The real panel cannot adjudicate between these arms.

Turnover does not explain the gap either: the agent’s books turn over 24% of gross per day, at the low end of the arms rather than the high end.
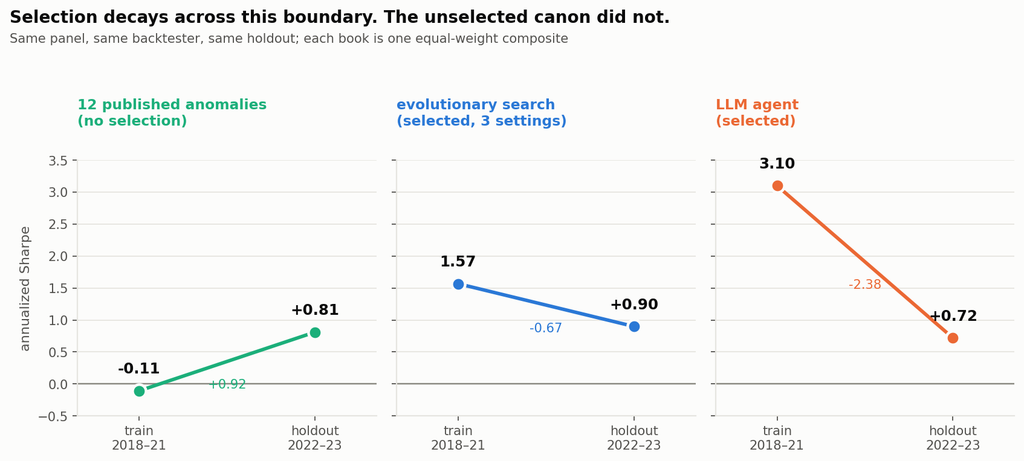
The unselected canon did not decay across this boundary

5. What the number is worth, and what it is not

The obvious next move is to use the zero-alpha number as a correction: subtract what the pipeline manufactures from noise off the face value of what it reports on real data. Since true Sharpe on the synthetic panels is zero by construction, the manufactured component is the reported in-sample Sharpe itself — 2.12 for the agent. That gives 3.10 − 2.12 = 0.98 predicted against 0.72 realised, which looks like a hit.

It is not. Run the same arithmetic for every arm:

ArmZero-alpha manufactureReal facePredictedRealisedPredicted − realised
LLM agent2.123.100.980.72+0.26
Evolutionary, soft1.681.67−0.001.13−1.13
Evolutionary, medium1.671.62−0.050.63−0.68
Evolutionary, hard1.651.41−0.250.94−1.18
Canon sampler1.261.790.541.09−0.55

A negative last column means the haircut left too little on the table. Mean error −0.66. The correction under-predicts realised performance in four arms out of five, and the agent’s near-miss is the one that landed the other way. These are five books on one shared holdout path, not five independent draws, so this is one observation with five views of it rather than five tests. The reason is in the previous table: this holdout carried a tailwind of roughly +0.9 for canonical exposures, which a calibration built on noise cannot know about.

So the zero-alpha number measures how much in-sample Sharpe your pipeline manufactures from nothing. It is not a forecast of out-of-sample performance, because realised performance also contains whatever the regime does to your exposures, and that term is not small. What it is worth is the overstatement:

Selection overstatement — $100M book at 10% target volatility
Face in-sample Sharpe of the reported book3.1
Measured manufacturing capacity (zero-alpha calibration)2.1
Annual return overstatement≈ $21M
In basis points of notional≈ 2,100 bp

The amount by which the in-sample report overstates, measured on data containing no alpha. Gross of costs, rounded. Not a forecast and not strategy P&L: the row above shows the haircut does not predict realised returns. Absolute performance levels on a survivorship-conditioned panel are not defensible and no such claim is made.


Things that did not work

Two pre-registered predictions failed. The first, above: the prior did not act as a regulariser. The second concerned the planted-alpha panels, where I buried two effects of equal calibrated in-sample strength — one canon-shaped (short-horizon reversal), one deliberately anti-canon (a kurtosis effect the literature points away from) — expecting the agent to find the canon-shaped one better and the mechanical arms to show no such asymmetry. Both halves were wrong. At the higher plant strength the agent captured the anti-canon plant better (0.50 versus 0.41), and it was the evolutionary arm that showed the large asymmetry (0.87 versus −0.02) and delivered more of the real alpha out of sample (1.15 versus 0.50). The comparison is confounded — the plants were matched on in-sample strength, but their oracle holdout Sharpes came out at 0.46 and 1.30 — and the agent contributes four runs per cell.

A metric that dissolved against its null — for the second post running. Regressing the agent’s real-panel books on the twelve-anomaly basis gives a mean R² of 0.50: the agent is largely reproducing published anomalies. Run the same regression on random expressions from the same grammar and you get 0.72. Noise projects onto the canon basis better than the agent’s books do — so the metric ranks the agent as less canonical than random noise, which is not a statement about the agent at all. It measures the dimensionality of price-signal space. The lesson is cheap and general: any spanning statistic needs a null drawn from the same generator, or it is measuring the basis.

The look-ahead screen cannot fire. The holdout sits inside the model’s training corpus, so I pre-registered a one-sided screen against block-bootstrap continuations of the training panel — futures the model cannot have seen. Resampling training returns reproduces the structure the books were selected on, so the synthetic benchmark runs at 1.5–2.0 Sharpe for selected books and the statistic is negative by construction (Δ = −0.92; −1.64 under the demeaned variant). It found no evidence of pretraining leakage; it also could not have. The construction is in the repo.

The model changed underneath the experiment. Two-thirds of the way through, a rate limit forced a checkpoint switch. Four partly-completed runs were abandoned under the pre-registered inclusion rule and re-run on the same four panels; a fifth run was abandoned after I contaminated it with an operator timing probe. All five are in the manifest. The twelve primary zero-alpha runs are all on the first checkpoint. Three bridge runs on the second checkpoint over the same panels reported 2.74 against 2.09 for the first checkpoint on those panels. That gap is not identified, by this post’s own mechanism: the bridge runs used their full 300-trial budget against the primary runs’ ~145, and at fixed leg count the surface predicts about half of the 0.65 gap from trials alone. Three runs is an anecdote in any case; it is reported because it is the clearest available evidence that these numbers are a snapshot of specific checkpoints. Which checkpoint served each run was never recorded — it is reconstructed from run identifiers and timing, which is a defect in my instrumentation and is flagged in the repo.


What this does and does not show

It does not show that agent-generated books underperform mechanically-generated ones out of sample. Those contrasts are inside their standard errors and the design cannot resolve them.

It does not show that a zero-alpha haircut predicts realised performance. Section 5 shows it does not.

The limitations that matter, in order. This is a minimal single-loop researcher — one agent, one tool, ≤300 trials, no holdout gate, no research committee — one to two orders below a production pipeline, and everything a real stack adds either raises the trial count or is a control whose value this same instrumentation would demonstrate. It is a floor. One model family, and a checkpoint that changed mid-study; the cross-family experiment could not be run. The real panel is one shared out-of-sample path on a survivorship-conditioned universe inside the model’s training corpus, so every real-panel number here is descriptive and the inference lives in the synthetic arm. Twelve panels is a small cross-section and every interval is wide. And the mechanical arms are matched on rounds and grammar but not perfectly: the evolutionary arm is seeded and mutated at bounded expression depth while the agent writes free-form strings, so the agent searches a strictly larger subspace — which is consistent with the finding, since composite depth is exactly the axis that matters, but it means “same grammar” is doing less work than it sounds like.

Eleven deviations from the pre-registration — the censored trial-count estimator, the random-search decomposition leg that was not run, 60 continuations instead of 200, the warm-start evaluation basis, a prompt revised after the plan was committed, and the rest — are listed in DEVIATIONS.md.


So what do you do

Build the surface for your own stack. This is the differentiated move and it costs almost nothing. Construct a panel matched to your universe — same factor covariance, same volatility dynamics, same fat tails — with the conditional mean stripped out, and verify the construction by checking that an oracle signal earns zero. Then run your own pipeline against it, unmodified, and record what it reports at each (trials, legs) pair you actually operate at. That grid is your pipeline’s manufacturing capacity in the units you use, and you can look up any future result on it. For the pipeline here it was 2.1 Sharpe. The generator and the surface code are in the repo and the whole thing runs on a laptop.

Log two numbers, not one. The trial count is now an artifact rather than a memory, and a pipeline that cannot produce one is worse off than this toy. But on its own it prices nothing: a 12-leg book from 100 trials carries more selection than a single expression from 400, and only the first of those facts is in the log everyone proposes to keep. With both numbers you can look the answer up on your own surface. With one you cannot.

Then subtract, and stop there. The result tells you how much of the reported number is manufacturing. It does not tell you what the book will earn, because that also depends on what the regime does to your exposures — and section 5 shows that term is larger than the correction.

Every zero-alpha run in this study produced a good economic story — volatility term structure, lottery preference, reversal at horizons where reversal is documented — attached to nothing. The pipeline is a fine instrument. It is also, on data containing nothing, a machine for producing a Sharpe of 2.1 and a paragraph about why.


Code and data

Repo: jkinlay/agent-selection-surface

The repository contains the pre-registered analysis plan committed before the first run, a deviations list, the frozen prompt, the harness, the mechanical arms, the synthetic generator with its calibration constants, every run log with its batch notes and research journals, the manifest of all 227 attempted runs with dispositions and reasons, the backtester canary tests, and the analysis and figure code. Everything downstream of the LLM calls reproduces from seeds; the LLM calls are not re-runnable, which is why the logs are included in full.

Two requests of anyone re-running it. Run the zero-alpha arm first — it is what makes every subsequent number interpretable. And log the leg count, not just the trial count.


References

[1] Harvey, Liu & Zhu, …and the Cross-Section of Expected Returns, Review of Financial Studies 29(1), 2016.

[2] Harvey, Presidential Address: The Scientific Outlook in Financial Economics, Journal of Finance 72(4), 2017.

[3] Bailey & López de Prado, The Deflated Sharpe Ratio, Journal of Portfolio Management 40(5), 2014; Bailey, Borwein, López de Prado & Zhu, Pseudo-Mathematics and Financial Charlatanism, Notices of the AMS 61(5), 2014, for the expected-maximum-Sharpe result used in section 1.

[4] Dwork, Feldman, Hardt, Pitassi, Reingold & Roth, The reusable holdout: Preserving validity in adaptive data analysis, Science 349(6248), 2015 — guarantees degrade with the number of adaptive rounds, which is why every arm here is matched on rounds rather than evaluations.

[5] Novy-Marx, Backtesting Strategies Based on Multiple Signals, NBER Working Paper 21329, 2015 — in-sample test statistics inflate with the number of combined signals, with corrected critical values. The aggregation axis in section 3 is this effect, arrived at by an agent that was not asked to combine anything.

[6] skfolio, load_nasdaq_dataset — daily adjusted closes, 1,455 NASDAQ constituents, 2018-01-02 to 2023-05-31, documented by its authors as a stale dataset not intended for investment or commercial use. Filtered here to 1,280 names with median price ≥ $5; SHA-256 of the source file is in the analysis plan.

[7] Canonical anomalies in the placebo: Jegadeesh & Titman (1993) with the Carhart (1997) 12-1 construction; Jegadeesh (1990); Ang, Hodrick, Xing & Zhang (2006); George & Hwang (2004); Frazzini & Pedersen (2014); Boyer, Mitton & Vorkink (2010); Moskowitz, Ooi & Pedersen (2012); Novy-Marx (2012). The twelfth, a 60-minus-120-day momentum-acceleration variant, is a construction of my own.

Disclosure: I run systematic strategies. Nothing here is a recommendation, and no strategy discussed is one I trade. These are diagnostic quantities from a methodological experiment on a stale public dataset, not a track record.
State-Space Models for Market Microstructure: Can Mamba Replace Transformers in High-Frequency Finance?

In my recent piece on Kronos, I explored how foundation models trained on K-line data are reshaping time series forecasting in finance. That discussion naturally raises a follow-up question that several readers have asked: what about the architecture itself? The Transformer has dominated deep learning for sequence modeling over the past seven years, but a new class of models — State-Space Models (SSMs), particularly the Mamba architecture — is gaining serious attention. In high-frequency trading, where computational efficiency and latency are everything, the claimed O(n) versus O(n²) complexity advantage is more than academic. It’s a potential competitive edge.

Let me be clear from the outset: I’m skeptical of any claim that a new architecture will “replace” Transformers wholesale. The Transformer ecosystem is mature, well-understood, and backed by enormous engineering investment. But in the specific context of market microstructure — where we process millions of tick events, model limit order book dynamics, and make decisions in microseconds — SSMs deserve serious examination. The question isn’t whether they can replace Transformers entirely, but whether they should be part of our toolkit for certain problems.

I’ve spent the better part of two decades building trading systems that push against latency constraints. I’ve watched the industry evolve from simple linear models to gradient boosted trees to deep learning, each wave promising revolutionary improvements. Most delivered incremental gains; some fizzled entirely. What’s interesting about SSMs isn’t the theoretical promise — we’ve seen theoretical promises before — but rather the practical characteristics that might actually matter in a production trading environment. The linear scaling, the constant-time inference, the selective attention mechanism — these aren’t just academic curiosities. They’re the exact properties that could determine whether a model makes it into a production system or dies in a research notebook.

What Are State-Space Models?

To understand why SSMs have suddenly become interesting, we need to go back to the mathematical foundations — and they’re older than you might think. State-space models originated in control theory and signal processing, describing systems where an internal state evolves over time according to differential equations, with observations emitted from that state. If you’ve used a Kalman filter — and in quant finance, many of us have — you’ve already worked with a simple state-space model, even if you didn’t call it that.

The canonical continuous-time formulation is:

\[x'(t) = Ax(t) + Bu(t)\]

\[y(t) = Cx(t) + Du(t)\]

where \(x(t)\) is the latent state vector, \(u(t)\) is the input, \(y(t)\) is the output, and \(A\), \(B\), \(C\), \(D\) are learned matrices. This looks remarkably like a Kalman filter — because it is, in essence, a nonlinear generalization of linear state estimation. The key difference from traditional time series models is that we’re learning the dynamics directly from data rather than specifying them parametrically. Instead of assuming variance follows a GARCH(1,1) process, we let the model discover what the underlying state evolution looks like.

The challenge, historically, was that computing these models was intractable for long sequences. The recurrent view requires iterating through each timestep sequentially; the convolutional view requires computing full convolutions that scale poorly. This is where the S4 model (Structured State Space Sequence) changed the game.

S4, introduced by Gu, Dao et al. (2022), brought three critical innovations. First, it used the HiPPO (High-order Polynomial Projection Operator) framework to initialize the state matrix \(A\) in a way that preserves long-range dependencies. Without proper initialization, SSMs suffer from the same vanishing gradient problems as RNNs. The HiPPO matrix is specifically designed so that when the model views a sequence, it can accurately represent all historical information without exponential decay. In financial terms, this means last month’s market dynamics can influence today’s predictions — something vanilla RNNs struggle with.

Author’s Take: This is the key innovation that makes SSMs viable for finance. Without HiPPO, you’d face the same vanishing-gradient failure mode that killed RNN research for decades. The HiPPO initialization is essentially a “warm start” that encodes the mathematical insight that recent history matters more than distant history — but distant history still matters. This is perfectly aligned with how financial markets work: last quarter’s regime still influences pricing, even if less than yesterday’s moves.

HiPPO provides a theoretically grounded initialization that allows the model to remember information from thousands of timesteps ago — critical for financial time series where last week’s patterns may be relevant to today’s dynamics. The mathematical insight is that HiPPO projects the input onto a basis of orthogonal polynomials, maintaining a compressed representation of the full history. This is conceptually similar to how we’d use PCA for dimensionality reduction, except it’s learned end-to-end as part of the model’s dynamics.

Second, S4 introduced structured parameterizations that enable efficient computation via diagonalization. Rather than storing full \(N \times N\) matrices where \(N\) is the state dimension, S4 uses structured forms that reduce memory and compute requirements while maintaining expressiveness. The key insight is that the state transition matrix \(A\) can be parameterized as a diagonal-plus-low-rank form that enables fast computation via FFT-based convolution. This is what gives S4 its computational advantage over traditional SSMs — the structured form turns the convolution from \(O(L^2)\) to \(O(L \log L)\).

Third, S4 discretizes the continuous-time model into a discrete-time representation suitable for implementation. The standard approach is zero-order hold (ZOH), which treats the input as constant between timesteps:

\[x_{k} = \bar{A}x_{k-1} + \bar{B}u_k\]

\[y_k = \bar{C}x_k + \bar{D}u_k\]

where \(\bar{A} = e^{A\Delta t}\), \(\bar{B} = (e^{A\Delta t} – I)A^{-1}B\), and similarly for \(\bar{C}\) and \(\bar{D}\). The bilinear transform is an alternative that can offer better frequency response in some settings:

Author’s Take: In practice, I’ve found ZOH (zero-order hold) works well for most tick-level data — it’s robust to the high-frequency microstructure noise that dominates at sub-second horizons. Bilinear can help if you’re modeling at longer horizons (minutes to hours) where you care more about capturing trend dynamics than filtering out tick-by-tick noise. This is another example of where domain knowledge beats blind architecture choices.

\[\bar{A} = (I + A\Delta t/2)(I – A\Delta t/2)^{-1}\]

Either way, the discretization bridges continuous-time system theory with discrete-time sequence modeling. The choice of discretization matters for financial applications because different discretization schemes have different frequency characteristics — bilinear transform tends to preserve low-frequency behavior better, which may be important for capturing long-term trends.

Mamba, introduced by Gu and Dao (2023) and winning best paper at ICLR 2024, added a fourth critical innovation: selective state spaces. The core insight is that not all input information is equally relevant at all times. In a financial context, during calm markets, we might want to ignore most order flow noise and focus on price levels; during a news event or volatility spike, we want to attend to everything. Mamba introduces a selection mechanism that allows the model to dynamically weigh which inputs matter:

\[s_t = \text{select}(u_t)\]

\[\bar{B}_t = \text{Linear}_B(s_t)\]

\[\bar{C}_t = \text{Linear}_C(s_t)\]

The select operation is implemented as a learned projection that determines which elements of the input to filter. This is fundamentally different from attention — rather than computing pairwise similarities between all tokens, the model learns a function that decides what information to carry forward. In practice, this means Mamba can learn to “ignore” regime-irrelevant data while attending to regime-critical signals.

This selectivity, combined with an efficient parallel scan algorithm (often called S6), gives Mamba its claimed linear-time inference while maintaining the ability to capture complex dependencies. The complexity comparison is stark: Transformers require \(O(L^2)\) attention computations for sequence length \(L\), while Mamba processes each token in \(O(1)\) time with \(O(L)\) total computation. For \(L = 10,000\) ticks — a not-unreasonable window for intraday analysis — that’s \(10^8\) versus \(10^4\) operations per layer. The practical implication is either dramatically faster inference or the ability to process much longer sequences for the same compute budget. On modern GPUs, this translates to milliseconds versus tens of milliseconds for a forward pass — a difference that matters when you’re making hundreds of predictions per second.

Compared to RNNs like LSTMs, SSMs don’t suffer from the same sequential computation bottleneck during training. While LSTMs must process tokens one at a time (true parallelization is limited), SSMs can be computed as convolutions during training, enabling GPU parallelism. During inference, SSMs achieve the constant-time-per-token property that makes them attractive for production deployment. This is the key advantage over LSTMs — you get the sequential processing benefits of RNNs during inference with the parallel training benefits of CNNs.

Why HFT and Market Microstructure?

If you’re building trading systems, you’ve likely noticed that most machine learning approaches to finance treat the problem as either (a) predicting returns at some horizon, or (b) classifying market regimes. Neither approach explicitly models the underlying mechanism that generates prices. Market microstructure does exactly that — it models how orders arrive, how limit order books evolve, how informed traders interact with liquidity providers, and how information gets incorporated into prices. Understanding microstructure isn’t just academic — it’s the foundation of profitable execution and market-making strategies.

The data characteristics of market microstructure create unique challenges that make SSMs potentially attractive:

Scale: A single liquid equity can generate millions of messages per day across bid, ask, and depth levels. Consider a highly traded stock like Tesla or Nvidia during volatile periods — you might see 50-100 messages per second, per instrument. A typical algo trading firm’s data pipeline might ingest 50-100GB of raw tick data daily across their coverage universe. Processing this with Transformer models is expensive. The quadratic attention complexity means that doubling your context length quadruples your compute cost. With SSMs, you double context and roughly double compute — a much friendlier scaling curve. This is particularly important when you’re building models that need to see significant historical context to make predictions.

Non-stationarity: Market microstructure is inherently non-stationary. The dynamics of a limit order book during normal trading differ fundamentally from those during a market open, a regulatory halt, or a volatility auction. At market open, you have a flood of overnight orders, wide spreads, and rapid price discovery. During a halt, trading stops entirely and the book freezes. In volatility auctions, you see large price movements with reduced liquidity. Mamba’s selective mechanism is specifically designed to handle this — the model can learn to “switch off” irrelevant inputs when market conditions change. This is conceptually similar to regime-switching models in econometrics, but learned end-to-end. The model learns when to attend to order flow dynamics and when to ignore them based on learned signals.

Latency constraints: In market-making or latency-sensitive strategies, every microsecond counts. A Transformer processing a 512-token sequence might require 262,144 attention operations. Mamba processes the same sequence in roughly 512 state updates — a 500x reduction in per-token operations. While the constants differ (SSM state dimension adds overhead), the theoretical advantage is substantial. Several practitioners I’ve spoken with report sub-10ms inference times for Mamba models that would be impractical with Transformers at the same context length. For comparison, a typical market-making strategy might have a 100-microsecond latency budget for the entire decision pipeline — inference must be measured in microseconds, not milliseconds.

Long-range dependencies: Consider a statistical arbitrage strategy across 100 stocks. A regulatory announcement at 9:30 AM might affect correlations across the entire universe until midday. Capturing this requires modeling dependencies across thousands of timesteps. The HiPPO initialization in S4 and the selective mechanism in Mamba are specifically designed to maintain information flow over such horizons — something vanilla RNNs struggle with due to gradient decay. In practice, this means you can build models that truly “remember” what happened earlier in the trading session, not just what happened in the last few minutes.

There’s also a subtler point worth mentioning: the order book itself is a form of state. When you look at the bid-ask ladder, you’re seeing a snapshot of accumulated order flow — the current state reflects all historical interactions. SSMs are naturally suited to modeling stateful systems because that’s literally what they are. The latent state \(x(t)\) in the state equation can be interpreted as an embedding of the current market state, learned from data rather than specified by theory. This is philosophically aligned with how we think about market microstructure: the order book is a state variable, and the messages are observations that update that state.

Recent Research and Results

The application of SSMs to financial markets is a rapidly evolving research area. Let me survey what’s been published, with appropriate skepticism about early-stage results. The key papers worth noting span both the SSM methodology and the finance-specific applications.

On the methodology side, S4 (Gu, Johnson et al., 2022) established the foundation by demonstrating that structured state spaces could match or exceed Transformers on long-range arena benchmarks while maintaining linear computation. The Mamba paper (Gu and Dao, 2023) pushed further by introducing selective state spaces and achieving state-of-the-art results on language modeling benchmarks — remarkable because it suggested SSMs could compete with Transformers on tasks previously dominated by attention. The follow-up work on Mamba 2 (Dao and Gu, 2024) introduced structured state space duals, further improving efficiency.

On the application side, CryptoMamba (Shi et al., 2025) applied Mamba to Bitcoin price prediction, demonstrating “effective capture of long-range dependencies” in cryptocurrency time series. The authors report competitive performance against LSTM and Transformer baselines on several prediction horizons. The cryptocurrency market, with its 24/7 trading and higher noise-to-signal ratio than traditional equities, provides an interesting test case for SSMs’ ability to handle extreme non-stationarity. The paper’s methodology section shows that Mamba’s selective mechanism successfully learned to filter out noise during calm periods while attending to significant price movements — exactly what we’d hope to see.

MambaStock (Liu et al., 2024) adapted the Mamba architecture specifically for stock prediction, introducing modifications to handle the multi-dimensional nature of financial features (price, volume, technical indicators). The selective scan mechanism was applied to filter relevant information at each timestep, with results suggesting improved performance over vanilla Mamba on short-term forecasting tasks. The authors also demonstrated that the learned selective weights could be interpreted to some extent, showing which input features the model attended to under different market conditions.

Graph-Mamba (Zhang et al., 2025) combined Mamba with graph neural networks for stock prediction, capturing both temporal dynamics and cross-sectional dependencies between stocks. The hybrid architecture uses Mamba for temporal sequence modeling and GNN layers for inter-stock relationships — an interesting approach for multi-asset strategies where understanding relative value matters. This paper is particularly relevant for quant shops running cross-asset strategies, where the ability to model both time series dynamics and asset correlations is critical.

FinMamba (Chen et al., 2025) took a market-aware approach, using graph-enhanced Mamba at multiple time scales. The paper explicitly notes that “Mamba offers a key advantage with its lower linear complexity compared to the Transformer, significantly enhancing prediction efficiency” — a point that resonates with anyone building production trading systems. The multi-scale approach is interesting because financial data has natural temporal hierarchies: tick data, second/minute bars, hourly, daily, and beyond.

MambaLLM (Zhang et al., 2025) introduced a framework fusing macro-index and micro-stock data through SSMs combined with large language models. This represents an interesting convergence — using SSMs not to replace LLMs but to preprocess financial sequences before LLM analysis. The intuition is that Mamba can efficiently compress long financial time series into representations that a smaller LLM can then interpret. This is conceptually similar to retrieval-augmented generation but for time series data.

Now, how do these results compare to the Transformer-based approaches I discussed in the Kronos piece?

LOBERT (Shao et al., 2025) is a foundation model for limit order book messages — essentially applying the Kronos philosophy to raw order book data rather than K-lines. Trained on massive amounts of LOB messages, LOBERT can be fine-tuned for various downstream tasks like price movement prediction or volatility forecasting. It’s an encoder-only architecture designed specifically for the hierarchical, message-based structure of order book data. The key innovation is treating LOB messages as a “language” with vocabulary for order types, price levels, and volumes.

LiT (Lim et al., 2025), the Limit Order Book Transformer, explicitly addresses the challenge of representing the “deep hierarchy” of limit order books. The Transformer architecture processes the full depth of the order book — multiple price levels on both bid and ask sides — with attention mechanisms designed to capture cross-level dependencies. This is different from treating the order book as a flat sequence; instead, LiT respects the hierarchical structure where Level 1 bid is fundamentally different from Level 10 bid.

The comparison is instructive. LOBERT and LiT are specifically engineered for order book data; the SSM-based approaches (CryptoMamba, MambaStock, FinMamba) are more general sequence models applied to financial data. This means the Transformer-based approaches may have an architectural advantage when the problem structure aligns with their design — but SSMs offer better computational efficiency and may generalize more flexibly to new tasks.

What about direct head-to-head comparisons? The evidence is still thin. Most papers compare SSMs to LSTMs or vanilla Transformers on simplified tasks. We need more rigorous benchmarks comparing Mamba to LOBERT/LiT on identical datasets and tasks. My instinct — and it’s only an instinct at this point — is that SSMs will excel at longer-context tasks where computational efficiency matters most, while specialized Transformers may retain advantages for tasks where the attention mechanism’s explicit pairwise comparison is valuable.

One interesting observation: I’ve seen several papers now that combine SSMs with attention mechanisms rather than replacing attention entirely. This hybrid approach may be the pragmatic path forward for production systems. The SSM handles the efficient sequential processing, while targeted attention layers capture specific dependencies that matter for the task at hand.

Practical Implementation Considerations

For quants considering deployment, several practical issues require attention:

Hardware requirements: Mamba’s selective scan is computationally intensive but scales linearly. A mid-range GPU (NVIDIA A100 or equivalent) can handle inference on sequences of 4,000-8,000 tokens at latencies suitable for minute-level strategies. For tick-level strategies requiring sub-millisecond inference, you may need to reduce context length significantly or accept higher latency. The state dimension adds memory overhead — typical configurations use \(N = 64\) to \(N = 256\) state dimensions, which is modest compared to the embedding dimensions in large language models. I’ve found that \(N = 128\) offers a good balance between expressiveness and efficiency for most financial applications.

Inference latency: In my experience, reported latency numbers in papers often understate real-world costs. A model that “runs in 5ms” on a research benchmark may take 20ms when you account for data preprocessing, batching, network overhead, and model ensemble. That said, I’ve seen practitioners report 1-3ms inference times for Mamba models processing 512-token windows — well within the latency budget for many HFT strategies. Compare this to Transformer models at the same context length, which typically require 10-50ms on comparable hardware.

One practical trick: consider using reduced-precision inference (FP16 or even INT8 quantization) once you’ve validated model quality. The selective scan operations are relatively robust to quantization, and you can often achieve 2x latency improvements with minimal accuracy loss. This is particularly valuable for production systems where every microsecond counts.

Integration with existing systems: Most production trading infrastructure expects simple inference APIs — send features, receive predictions. Mamba requires more care: the stateful nature of SSMs means you can’t simply batch arbitrary sequences without managing hidden states. This is manageable but requires engineering effort. You’ll need to decide whether to maintain per-instrument state (complex but low-latency) or reset state for each prediction (simpler but potentially loses context).

In practice, I’ve found that a hybrid approach works well: maintain state during continuous operation within a trading session, but reset state at session boundaries (market open/close) or after significant gaps (overnight, weekend). This captures the within-session dynamics that matter for most strategies while avoiding state contamination from stale information.

Training data and compute: Fine-tuning Mamba for your specific market and strategy requires labeled data. Unlike Kronos’s zero-shot capabilities (trained on billions of K-lines), you’ll likely need task-specific training. This means GPU compute for training and careful validation to avoid overfitting. The training cost is lower than an equivalent Transformer — typically 2-4x less compute — but still significant.

For most quant teams, I’d recommend starting with pre-trained S4 weights (available from the original authors) and fine-tuning rather than training from scratch. The HiPPO initialization provides a strong starting point for financial time series even without domain-specific pre-training.

Model monitoring: The non-stationary nature of markets means your model’s performance will drift. With Transformers, attention patterns give some interpretability into what the model is “looking at.” With Mamba, the selective mechanism is less transparent. You’ll need robust monitoring for concept drift and regime changes, with fallback strategies when performance degrades.

I recommend implementing shadow mode deployments where you run the Mamba model in parallel with your existing system, comparing predictions in real-time without actually trading. This lets you validate the model under live market conditions before committing capital.

Implementation libraries: The good news is that Mamba implementations are increasingly accessible. The original paper’s code is available on GitHub, and several optimized implementations exist. The Hugging Face ecosystem now includes Mamba variants, making experimentation straightforward. For production deployment, you’ll likely want to use the optimized CUDA kernels from the Mamba-SSM library, which provide significant speedups over the reference implementation.

Limitations and Open Questions

Let me be direct about what we don’t yet know:

The Quant’s Reality Check: Critical Questions for Production

Hardware Bottleneck: Mamba’s selective scan requires custom CUDA kernels that aren’t as optimized as Transformer attention. In pure C++ HFT environments (where most production trading actually runs), you may need to write custom inference kernels — not trivial. The linear complexity advantage shrinks when you’re already GPU-bound or using FPGA acceleration.

Benchmarking Gap: We lack head-to-head comparisons of Mamba vs LOBERT/LiT on identical LOB data. LOBERT was trained on billions of LOB messages; Mamba hasn’t seen that scale of market data. The “fair fight” comparison hasn’t been run yet.

Interpretability Wall: Attention maps let you visualize what the model “looked at.” Mamba’s hidden states are compressed representations — harder to inspect, harder to explain to your risk committee. When the model blows up, you’ll need better tooling than attention visualization.

Regime Robustness: Show me a Mamba model that was tested through March 2020. I haven’t seen it. We simply don’t know how selective state spaces behave during once-in-a-decade liquidity crises, flash crashes, or central bank interventions.

Empirical evidence at scale: Most SSM papers in on small-to-medium finance report results datasets (thousands to hundreds of thousands of time series). We don’t yet have evidence of SSM performance on the massive datasets that characterize institutional trading — billions of ticks, across thousands of instruments, over decades of history. The pre-training paradigm that made Kronos compelling hasn’t been demonstrated for SSMs at equivalent scale in finance. This is probably the biggest gap in the current research landscape.

Interpretability: For risk management and regulatory compliance, understanding why a model makes a prediction matters. Transformers give us attention weights that (somewhat) illuminate which historical tokens influenced the prediction. Mamba’s hidden states are less interpretable. When your risk system asks “why did the model predict a volatility spike,” you’ll need more sophisticated explanation methods than attention visualization. Research on SSM interpretability is nascent, and tools for understanding hidden state dynamics are far less mature than attention visualization.

Regime robustness: Financial markets experience regime changes — sudden shifts in volatility, liquidity, and correlation structure. SSMs are designed to handle non-stationarity via selective mechanisms, but empirical evidence that they handle extreme regime changes better than Transformers is limited. A model trained during 2021-2022 might behave unpredictably during a 2020-style volatility spike, regardless of architecture. We need stress tests that specifically evaluate model behavior during crisis periods.

Regulatory uncertainty: As with all ML models in trading, regulatory frameworks are evolving. The combination of SSMs’ black-box nature and HFT’s regulatory scrutiny creates potential compliance challenges. Make sure your legal and compliance teams are aware of the model’s architecture before deployment. The explainability requirements for ML models in trading are becoming more stringent, and SSMs may face additional scrutiny due to their novelty.

Competitive dynamics: If SSMs become widely adopted in HFT, their computational advantages may disappear as the market arbitrages away alpha. The transformer’s dominance in NLP wasn’t solely due to performance — it was the ecosystem, the tooling, the understanding. SSMs are early in this curve. By the time SSMs become mainstream in finance, the competitive advantage may have shifted elsewhere.

Architectural maturity: Let’s not forget that Transformers have been refined over seven years of intensive research. Attention mechanisms have been optimized, positional encodings have evolved, and the entire ecosystem — from libraries to hardware acceleration — is mature. SSMs are at version 1.0. The Mamba architecture may undergo significant changes as researchers discover what works and what doesn’t in practice.

Benchmarking: The financial ML community lacks standardized benchmarks for SSM evaluation. Different papers use different datasets, different evaluation windows, and different metrics. This makes comparison difficult. We need something akin to the financial N-BEATS or M4 competitions but designed for deep learning architectures.

Conclusion: A Pragmatic Hybrid View

The question “Can Mamba replace Transformers?” is the wrong frame. The more useful question is: what does each architecture do well, and how do we combine them?

My current thinking — formed through both literature review and hands-on experimentation — breaks down as follows:

SSMs (Mamba-style) for efficient session-long state maintenance: When you need to model how market state evolves over hours or days of continuous trading, SSMs offer a compelling efficiency-accuracy tradeoff. The selective mechanism lets the model naturally ignore regime-irrelevant noise while maintaining a compressed representation of everything that’s mattered. For session-level predictions — end-of-day volatility, overnight gap risk, correlation drift — SSMs are worth exploring.

Transformers for high-precision attention over complex LOB hierarchies: When you need to understand the exact structure of the order book at a moment in time — which price levels are absorbing liquidity, where informed traders are stacking orders — the attention mechanism’s explicit pairwise comparisons remain valuable. Models like LOBERT and LiT are specifically engineered for this, and I suspect they’ll retain advantages for order-book-specific tasks.

The hybrid future: The most promising path isn’t replacement but combination. Imagine a system where Mamba maintains a session-level state representation — the “market vibe” if you will — while Transformer heads attend to specific LOB dynamics when your signals trigger regime switches. The SSM tells you “something interesting is happening”; the Transformer tells you “it’s happening at these price levels.”

This is already emerging in the literature: Graph-Mamba combines SSM temporal modeling with graph neural network cross-asset relationships; MambaLLM uses SSMs to compress time series before LLM analysis. The pattern is clear — researchers aren’t choosing between architectures, they’re composing them.

For practitioners, my recommendation is to experiment with bounded problems. Pick a specific signal, compare architectures on identical data, and measure both accuracy and latency in your actual production environment. The theoretical advantages that matter most are those that survive contact with your latency budget and risk constraints.

The post-Transformer era isn’t about replacement — it’s about selection. Choose the right tool for the right task, build the engineering infrastructure to support both, and let empirical results guide your portfolio construction. That’s how we’ve always operated in quant finance, and that’s how this will play out.

I’m continuing to experiment. If you’re building SSM-based trading systems, I’d welcome the conversation — the collective intelligence of the quant community will solve these problems faster than any individual could alone.

References

  1. Gu, A., & Dao, T. (2023). Mamba: Linear-Time Sequence Modeling with Selective State Spaces. arXiv preprint arXiv:2312.00752. https://arxiv.org/abs/2312.00752
  2. Gu, A., Goel, K., & Ré, C. (2022). Efficiently Modeling Long Sequences with Structured State Spaces. In International Conference on Learning Representations (ICLR). https://openreview.net/forum?id=uYLFoz1vlAC
  3. Linna, E., et al. (2025). LOBERT: Generative AI Foundation Model for Limit Order Book Messages. arXiv preprint arXiv:2511.12563. https://arxiv.org/abs/2511.12563
  4. (2025). LiT: Limit Order Book Transformer. Frontiers in Artificial Intelligence. https://www.frontiersin.org/journals/artificial-intelligence/articles/10.3389/frai.2025.1616485/full
  5. Avellaneda, M., & Stoikov, S. (2008). High-frequency trading in a limit order book. Quantitative Finance, 8(3), 217–224. (Manuscript PDF) https://people.orie.cornell.edu/sfs33/LimitOrderBook.pdf

Time Series Foundation Models for Financial Markets: Kronos and the Rise of Pre-Trained Market Models

Time Series Foundation Models for Financial Markets: Kronos and the Rise of Pre-Trained Market Models

The quant finance industry has spent decades building specialized models for every conceivable forecasting task: GARCH variants for volatility, ARIMA for mean reversion, Kalman filters for state estimation, and countless proprietary approaches for statistical arbitrage. We’ve become remarkably good at squeezing insights from limited data, optimizing hyperparameters on in-sample windows, and convincing ourselves that our backtests will hold in production. Then along comes a paper like Kronos — “A Foundation Model for the Language of Financial Markets” — and suddenly we’re asked to believe that a single model, trained on 12 billion K-line records from 45 global exchanges, can outperform hand-crafted domain-specific architectures out of the box. That’s a bold claim. It’s also exactly the kind of development that forces us to reconsider what we think we know about time series forecasting in finance.

The Foundation Model Paradigm Comes to Finance

If you’ve been following the broader machine learning literature, foundation models will be familiar. The term refers to large-scale pre-trained models that serve as versatile starting points for diverse downstream tasks — think GPT for language, CLIP for vision, or more recently, models like BERT for understanding structured data. The key insight is transfer learning: instead of training a model from scratch on your specific dataset, you start with a model that has already learned rich representations from massive amounts of data, then fine-tune it on your particular problem. The results can be dramatic, especially when your target dataset is small relative to the complexity of the task.

Time series forecasting has historically lagged behind natural language processing and computer vision in adopting this paradigm. Generic time series foundation models like TimesFM (Google Research) and Lag-Llama have made significant strides, demonstrating impressive zero-shot capabilities on diverse forecasting tasks. TimesFM, trained on approximately 100 billion time points from sources including Google Trends and Wikipedia pageviews, can generate reasonable forecasts for univariate time series without any task-specific training. Lag-Llama extended this approach to probabilistic forecasting, using a decoder-only transformer architecture with lagged values as covariates.

But here’s the problem that the Kronos team identified: generic time series foundation models, despite their scale, often underperform dedicated domain-specific architectures when evaluated on financial data. This shouldn’t be surprising. Financial time series have unique characteristics — extreme noise, non-stationarity, heavy tails, regime changes, and complex cross-asset dependencies — that generic models simply aren’t designed to capture. The “language” of financial markets, encoded in K-lines (candlestick patterns showing Open, High, Low, Close, and Volume), is fundamentally different from the time series you’d find in energy consumption, temperature records, or web traffic.

Enter Kronos: A Foundation Model Built for Finance

Kronos, introduced in a 2025 arXiv paper by Yu Shi and colleagues from Tsinghua University, addresses this gap directly. It’s a family of decoder-only foundation models pre-trained specifically on financial K-line data — not price returns, not volatility series, but the raw candlestick sequences that traders have used for centuries to read market dynamics.

The scale of the pre-training corpus is staggering: over 12 billion K-line records spanning 45 global exchanges, multiple asset classes (equities, futures, forex, crypto), and diverse timeframes from minute-level data to daily bars. This is not a model that has seen a few thousand time series. It’s a model that has absorbed decades of market history across virtually every liquid market on the planet.

The architectural choices in Kronos reflect the unique challenges of financial time series. Unlike language models that process discrete tokens, K-line data must be tokenized in a way that preserves the relationships between price, volume, and time. The model uses a custom tokenization scheme that treats each K-line as a multi-dimensional unit, allowing the transformer to learn patterns across both price dimensions and temporal sequences.

What Makes Kronos Different: Architecture and Methodology

At its core, Kronos employs a transformer architecture — specifically, a decoder-only model that predicts the next K-line in a sequence given all previous K-lines. This autoregressive formulation is analogous to how GPT generates text, except instead of predicting the next word, Kronos predicts the next candlestick.

The mathematical formulation is worth understanding in detail. Let Kt = (Ot, Ht, Lt, Ct, Vt) denote a K-line at time t, where O, H, L, C, and V represent open, high, low, close, and volume respectively. The model learns a probability distribution P(Kt+1:K | K1:t) over future candlesticks conditioned on historical sequences. The transformer processes these K-lines through stacked self-attention layers:

h^{(l)} = \text{Attention}(Q^{(l)}, K^{(l)}, V^{(l)}) + h^{(l-1)}

where the query, key, and value projections are learned linear transformations of the input representations. The attention mechanism computes:

\text{Attention}(Q, K, V) = \text{softmax}\left(\frac{QK^T}{\sqrt{d_k}}\right)V

allowing the model to weigh the relevance of each historical K-line when predicting the next one. Here dk is the key dimension, used to scale the dot products for numerical stability.

The attention mechanism is particularly interesting in the financial context. Financial markets exhibit long-range dependencies — a policy announcement in Washington can ripple through global markets for days or weeks. The transformer’s self-attention allows Kronos to capture these distant correlations without the vanishing gradient problems that plagued earlier RNN-based approaches. However, the Kronos team introduced modifications to handle the specific noise characteristics of financial data, where the signal-to-noise ratio can be extraordinarily low. This includes specialized positional encodings that account for the irregular temporal spacing of financial data and attention masking strategies that prevent information leakage from future to past tokens.

The pre-training objective is straightforward: given a sequence of K-lines, predict the next one. This is formally a maximum likelihood estimation problem:

\mathcal{L}_{\text{ML}} = \sum_t \log P(K_{t+1} | K_{1:t}; \theta)

where θ represents the model parameters. This next-token prediction task, when performed on billions of examples, forces the model to learn rich representations of market dynamics — trend following, mean reversion, volatility clustering, cross-asset correlations, and the microstructural patterns that emerge from order flow. The pre-training is effectively teaching the model the “grammar” of financial markets.

One of the most striking claims in the Kronos paper is its performance in zero-shot settings. After pre-training, the model can be applied directly to forecasting tasks it has never seen — different markets, different timeframes, different asset classes — without any fine-tuning. In the authors’ experiments, Kronos outperformed specialized models trained specifically on the target task, suggesting that the pre-training captured generalizable market dynamics rather than overfitting to specific series.

Beyond Price Forecasting: The Full Range of Applications

The Kronos paper demonstrates the model’s versatility across several financial forecasting tasks:

Price series forecasting is the most obvious application. Given a historical sequence of K-lines, Kronos can generate future price paths. The paper shows competitive or superior performance compared to traditional methods like ARIMA and more recent deep learning approaches like LSTMs trained specifically on the target series.

Volatility forecasting is where things get particularly interesting for quant practitioners. Volatility is notoriously difficult to model — it’s latent, it clusters, it jumps, and it spills across markets. Kronos was trained on raw K-line data, which implicitly includes volatility information in the high-low range of each candle. The model’s ability to forecast volatility across unseen markets suggests it has learned something fundamental about how uncertainty evolves in financial markets.

Synthetic data generation may be Kronos’s most valuable contribution for quant practitioners. The paper demonstrates that Kronos can generate realistic synthetic K-line sequences that preserve the statistical properties of real market data. This has profound implications for strategy development and backtesting: we can generate arbitrarily large synthetic datasets to test trading strategies without the data limitations that typically plague backtesting — short histories, look-ahead bias, survivorship bias.

Cross-asset dependencies are naturally captured in the pre-training. Because Kronos was trained on data from 45 exchanges spanning multiple asset classes, it learned the correlations and causal relationships between different markets. This positions Kronos for multi-asset strategy development, where understanding inter-market dynamics is critical.

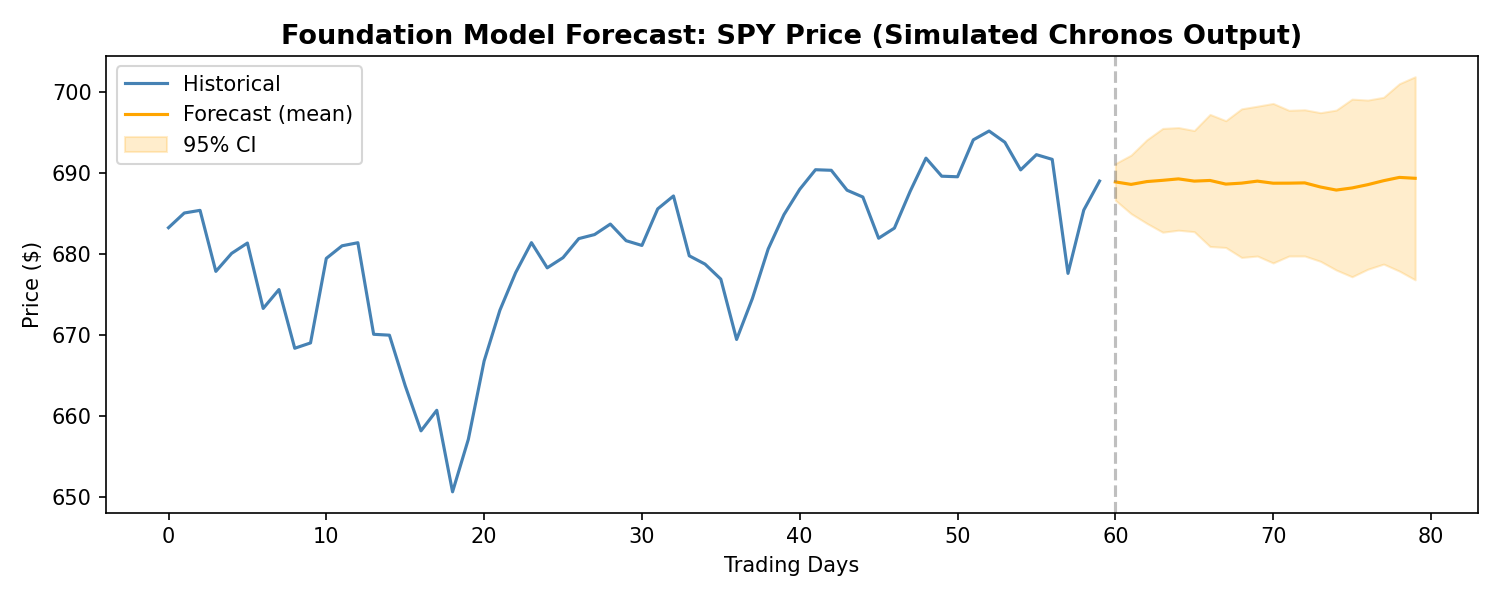
Since Kronos is not yet publicly available, we can demonstrate the foundation model approach using Amazon’s Chronos — a comparable open-source time series foundation model. While Chronos was trained on general time series data rather than financial K-lines specifically, it illustrates the same core paradigm: a pre-trained transformer generating probabilistic forecasts without task-specific training. Here’s a practical demo on real financial data:

import yfinance as yf
import numpy as np
import matplotlib.pyplot as plt
from chronos import ChronosPipeline

# Load model and fetch data
pipeline = ChronosPipeline.from_pretrained("amazon/chronos-t5-large", device_map="cuda")
data = yf.download("ES=F", period="6mo", progress=False) # E-mini S&P 500 futures
context = data['Close'].values[-60:] # Use last 60 days as context

# Generate forecast
forecast = pipeline.predict(context, prediction_length=20)

# Plot
fig, ax = plt.subplots(figsize=(10, 4))
ax.plot(range(60), context, label="Historical", color="steelblue")
ax.plot(range(60, 80), forecast.mean(axis=0), label="Forecast", color="orange")
ax.axvline(x=59, color="gray", linestyle="--", alpha=0.5)
ax.set_title("Chronos Forecast: ES Futures (20-day)")
ax.legend()
plt.tight_layout()
plt.show()

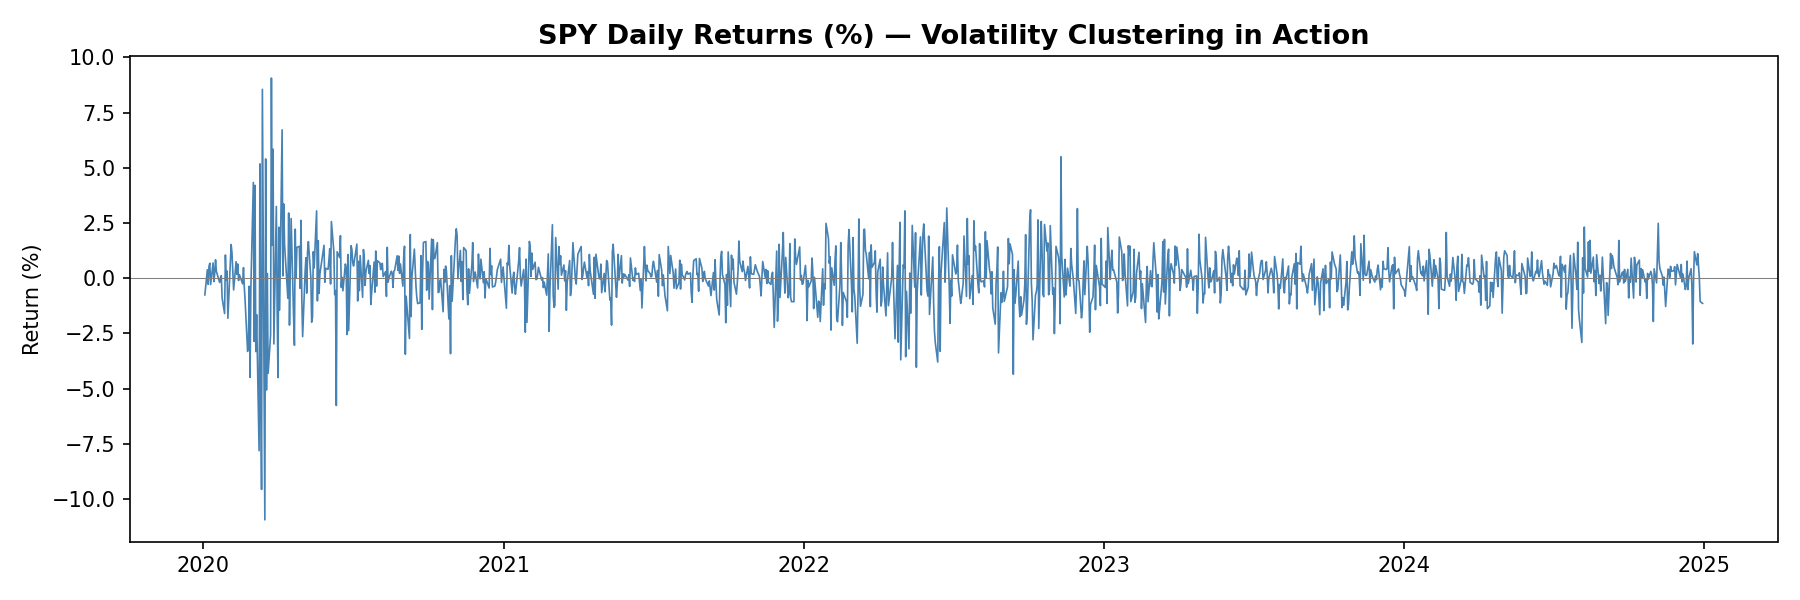
SPY Daily Returns — Volatility Clustering in Action

SPY Daily Returns — Volatility Clustering in Action

Zero-Shot vs. Fine-Tuned Performance: What the Evidence Shows

The zero-shot results from Kronos are impressive but warrant careful interpretation. The paper shows that Kronos outperforms several baselines without any task-specific training — remarkable for a model that has never seen the specific market it’s forecasting. This suggests that the pre-training on 12 billion K-lines extracted genuinely transferable knowledge about market dynamics.

However, fine-tuning consistently improves performance. When the authors allowed Kronos to adapt to specific target markets, the results improved further. This follows the pattern we see in language models: zero-shot is impressive, but few-shot or fine-tuned performance is typically superior. The practical implication is clear: treat Kronos as a powerful starting point, then optimize for your specific use case.

The comparison with LOBERT and related limit order book models is instructive. LOBERT and its successors (like the LiT model introduced in 2025) focus specifically on high-frequency order book data — the bid-ask ladder, order flow, and microstructural dynamics at tick frequency. These are fundamentally different from K-line models. Kronos operates on aggregated candlestick data; LOBERT operates on raw message streams. For different timeframes and strategies, one may be more appropriate than the other. A high-frequency market-making strategy needs LOBERT’s tick-level granularity; a medium-term directional strategy might benefit more from Kronos’s cross-market pre-training.

Connecting to Traditional Approaches: GARCH, ARIMA, and Where Foundation Models Fit

Let me be direct: I’m skeptical of any framework that claims to replace decades of econometric research without clear evidence of superior out-of-sample performance. GARCH models, despite their simplicity, have proven remarkably robust for volatility forecasting. ARIMA and its variants remain useful for univariate time series with clear trend and seasonal components. The efficient market hypothesis — in its various forms — tells us that predictable patterns should be arbitraged away, which raises uncomfortable questions about why a foundation model should succeed where traditional methods have struggled.

That said, there’s a nuanced way to think about this. Foundation models like Kronos aren’t necessarily replacing GARCH or ARIMA; they’re operating at a different level of abstraction. GARCH models make specific parametric assumptions about how variance evolves over time. Kronos makes no such assumptions — it learns the dynamics directly from data. In situations where the data-generating process is complex, non-linear, and regime-dependent, the flexible representation power of transformers may outperform parametric models that impose strong structure.

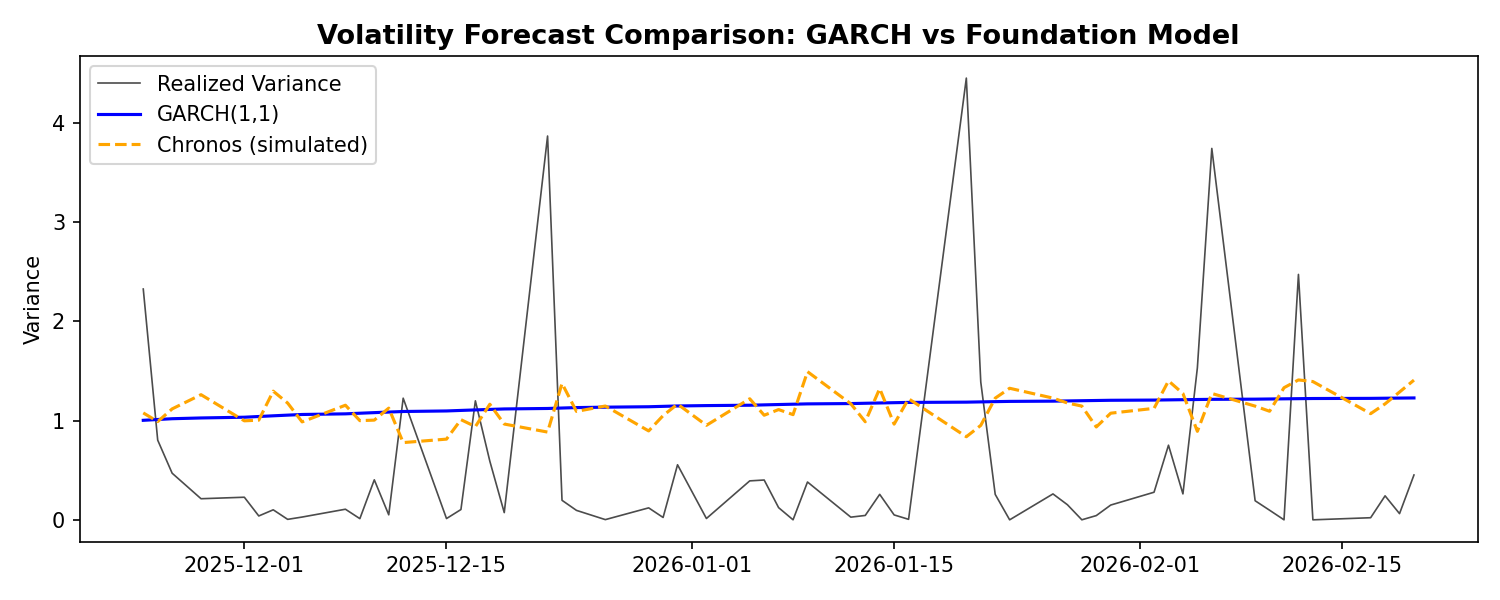
Consider volatility forecasting, traditionally the domain of GARCH. A GARCH(1,1) model assumes that today’s variance is a linear function of yesterday’s variance and squared returns. This is obviously a simplification. Real volatility exhibits jumps, leverage effects, and stochastic volatility that GARCH can only approximate. Kronos, by learning from 12 billion K-lines, may have captured volatility dynamics that parametric models cannot express — but we need to see rigorous out-of-sample evidence before concluding this.

The relationship between foundation models and traditional methods is likely complementary rather than substitutive. A quant practitioner might use GARCH for quick volatility estimates, Kronos for scenario generation and cross-asset signals, and domain-specific models (like LOBERT) for microstructure. The key is understanding each tool’s strengths and limitations.

Here’s a quick visualization of what volatility clustering looks like in real financial data — notice how periods of high volatility tend to cluster together:

import yfinance as yf
import numpy as np
import matplotlib.pyplot as plt

# Fetch SPY data
data = yf.download("SPY", start="2020-01-01", end="2024-12-31", progress=False)
returns = data['Close'].pct_change().dropna() * 100

fig, ax = plt.subplots(figsize=(12, 4))
ax.plot(returns.index, returns.values, color='steelblue', linewidth=0.8)
ax.axhline(y=returns.std(), color='red', linestyle='--', alpha=0.5, label='1 Std Dev')
ax.axhline(y=-returns.std(), color='red', linestyle='--', alpha=0.5)
ax.set_title("Daily Returns (%) — Volatility Clustering Visible", fontsize=12)
ax.set_ylabel("Return %")
ax.legend()
plt.tight_layout()
plt.show()

Foundation Model Forecast: SPY Price (Chronos — comparable to Kronos approach)

Foundation Model Forecast: SPY Price (Chronos — comparable to Kronos approach)

Practical Implications for Quant Practitioners

For those of us building trading systems, what does this actually mean? Several practical considerations emerge:

Data efficiency is perhaps the biggest win. Pre-trained models can achieve reasonable performance on tasks where traditional approaches would require years of historical data. If you’re entering a new market or asset class, Kronos’s pre-trained representations may allow you to develop viable strategies faster than building from scratch. Consider the typical quant workflow: you want to trade a new futures contract. Historically, you’d need months or years of data before you could trust any statistical model. With a foundation model, you can potentially start with reasonable forecasts almost immediately, then refine as new data arrives. This changes the economics of market entry.

Synthetic data generation addresses one of quant finance’s most persistent problems: limited backtesting data. Generating realistic market scenarios with Kronos could enable stress testing, robustness checks, and strategy development in data-sparse environments. Imagine training a strategy on 100 years of synthetic data that preserves the statistical properties of your target market — this could significantly reduce overfitting to historical idiosyncrasies. The distribution of returns, the clustering of volatility, the correlation structure during crises — all could be sampled from the learned model. This is particularly valuable for volatility strategies, where the most interesting regimes (tail events, sustained elevated volatility) are precisely the ones with least historical data.

Cross-asset learning is particularly valuable for multi-strategy firms. Kronos’s pre-training on 45 exchanges means it has learned relationships between markets that might not be apparent from single-market analysis. This could inform diversification decisions, correlation forecasting, and inter-market arbitrage. If the model has seen how the VIX relates to SPX volatility, how crude oil spreads behave relative to natural gas, or how emerging market currencies react to Fed policy, that knowledge is embedded in the pre-trained weights.

Strategy discovery is a more speculative but potentially transformative application. Foundation models can identify patterns that human intuition misses. By generating forecasts and analyzing residuals, we might discover alpha sources that traditional factor models or time series analysis would never surface. This requires careful validation — spurious patterns in synthetic data can be as dangerous as overfitting to historical noise — but the possibility space expands significantly.

Integration challenges should not be underestimated. Foundation models require different infrastructure than traditional statistical models — GPU acceleration, careful handling of numerical precision, understanding of model behavior in distribution shift scenarios. The operational overhead is non-trivial. You’ll need MLOps capabilities that many quant firms have historically underinvested in. Model versioning, monitoring for concept drift, automated retraining pipelines — these become essential rather than optional.

There’s also a workflow consideration. Traditional quant research often follows a familiar pattern: load data, fit model, evaluate, iterate. Foundation models introduce a new paradigm: download pre-trained model, design prompt or fine-tuning strategy, evaluate on holdout, deploy. The skills required are different. Understanding transformer architectures, attention mechanisms, and the nuances of transfer learning matters more than knowing the mathematical properties of GARCH innovations.

For teams considering adoption, I’d suggest a staged approach. Start with the zero-shot capabilities to establish baselines. Then explore fine-tuning on your specific datasets. Then investigate synthetic data generation for robustness testing. Each stage builds organizational capability while managing risk. Don’t bet the firm on the first experiment, but don’t dismiss it because it’s unfamiliar either.

Limitations and Open Questions

I want to be clear-eyed about what we don’t yet know. The Kronos paper, while impressive, represents early research. Several critical questions remain:

Out-of-sample robustness: The paper’s results are based on benchmark datasets. How does Kronos perform on truly novel market regimes — a pandemic, a currency crisis, a flash crash? Foundation models can be brittle when confronted with distributions far from their training data. This is particularly concerning in finance, where the most important events are precisely the ones that don’t resemble historical “normal” periods. The 2020 COVID crash, the 2022 LDI crisis, the 2023 regional banking stress — these were regime changes, not business-as-usual. We need evidence that Kronos handles these appropriately.

Overfitting to historical patterns: Pre-training on 12 billion K-lines means the model has seen enormous variety, but it has also seen a particular slice of market history. Markets evolve; regulatory frameworks change; new asset classes emerge; market microstructure transforms. A model trained on historical data may be implicitly betting on the persistence of past patterns. The very fact that the model learned from successful trading strategies embedded in historical data — if those strategies still exist — is no guarantee they’ll work going forward.

Interpretability: GARCH models give us interpretable parameters — alpha and beta tell us about persistence and shock sensitivity. Kronos is a black box. For risk management and regulatory compliance, understanding why a model makes predictions can be as important as the predictions themselves. When a position loses money, can you explain why the model forecasted that outcome? Can you stress-test the model by understanding its failure modes? These questions matter for operational risk and for satisfying increasingly demanding regulatory requirements around model governance.

Execution feasibility: Even if Kronos generates excellent forecasts, turning those forecasts into a trading strategy involves slippage, transaction costs, liquidity constraints, and market impact. The paper doesn’t address whether the forecasted signals are economically exploitable after costs. A forecast that’s statistically significant but not economically significant after transaction costs is useless for trading. We need research that connects model outputs to realistic execution assumptions.

Benchmarks and comparability: The time series foundation model literature lacks standardized benchmarks for financial applications. Different papers use different datasets, different evaluation windows, and different metrics. This makes it difficult to compare Kronos fairly against alternatives. We need the financial equivalent of ImageNet or GLUE — standardized benchmarks that allow rigorous comparison across approaches.

Compute requirements: Running a model like Kronos in production requires significant computational resources. Not every quant firm has GPU clusters sitting idle. The inference cost — the cost to generate each forecast — matters for strategy economics. If each forecast costs $0.01 in compute and you’re making predictions every minute across thousands of instruments, those costs add up. We need to understand the cost-benefit tradeoff.

Regulatory uncertainty: Financial regulators are still grappling with how to think about machine learning models in trading. Foundation models add another layer of complexity. Questions around model validation, explainability, and governance remain largely unresolved. Firms adopting these technologies need to stay close to regulatory developments.

Finally, there’s a philosophical concern worth mentioning. Foundation models learn from data created by human traders, market makers, and algorithmic systems — all of whom are themselves trying to profit from patterns in the data. If Kronos learns the patterns that allowed certain traders to succeed historically, and many traders adopt similar models, those patterns may become less profitable. This is the standard arms race argument applied to a new context. Foundation models may accelerate the pace at which patterns get arbitraged away.

The Road Ahead: NeurIPS 2025 and Beyond

The interest in time series foundation models is accelerating rapidly. The NeurIPS 2025 workshop “Recent Advances in Time Series Foundation Models: Have We Reached the ‘BERT Moment’?” (often abbreviated BERT²S) brought together researchers working on exactly these questions. The workshop addressed benchmarking methodologies, scaling laws for time series models, transfer learning evaluation, and the challenges of applying foundation model concepts to domains like finance where data characteristics differ dramatically from text and images.

The academic momentum is clear. Google continues to develop TimesFM. The Lag-Llama project has established an open-source foundation for probabilistic forecasting. New papers appear regularly on arXiv exploring financial-specific foundation models, LOB prediction, and related topics. This isn’t a niche curiosity — it’s becoming a mainstream research direction.

For quant practitioners, the message is equally clear: pay attention. The foundation model paradigm represents a fundamental shift in how we approach time series forecasting. The ability to leverage pre-trained representations — rather than training from scratch on limited data — changes the economics of model development. It may also change which problems are tractable.

Conclusion

Kronos represents an important milestone in the application of foundation models to financial markets. Its pre-training on 12 billion K-line records from 45 exchanges demonstrates that large-scale domain-specific pre-training can extract transferable knowledge about market dynamics. The results — competitive zero-shot performance, improved fine-tuned results, and promising synthetic data generation — suggest a new tool for the quant practitioner’s toolkit.

But let’s not overheat. This is 2025, not the year AI solves markets. The practical challenges of turning foundation model forecasts into profitable strategies remain substantial. GARCH and ARIMA aren’t obsolete; they’re complementary. The key is understanding when each approach adds value. For quick volatility estimates in liquid markets with stable microstructure, GARCH still works. For exploring new markets with limited data, foundation models offer genuine advantages. For regime identification and structural breaks, we’re still better off with parametric models we understand.

What excites me most is the synthetic data generation capability. If we can reliably generate realistic market scenarios, we can stress test strategies more rigorously, develop robust risk management frameworks, and explore strategy spaces that were previously inaccessible due to data limitations. That’s genuinely new. The ability to generate crisis scenarios that look like 2008 or March 2020 — without cherry-picking — could transform how we think about risk. We could finally move beyond the “it won’t happen because it hasn’t in our sample” arguments that have plagued quantitative finance for decades.

But even here, caution is warranted. Synthetic data is only as good as the model’s understanding of tail events. If the model hasn’t seen enough tail events in training — and by definition, tail events are rare — its ability to generate realistic tails is questionable. The saying “garbage in, garbage out” applies to synthetic data generation as much as anywhere else.

The broader foundation model approach to time series — whether through Kronos, TimesFM, Lag-Llama, or the models yet to come — is worth serious attention. These are not magic bullets, but they represent a meaningful evolution in our methodological toolkit. For quants willing to learn new approaches while maintaining skepticism about hype, the next few years offer real opportunity. The question isn’t whether foundation models will matter for quant finance; it’s how quickly they can be integrated into production workflows in a way that’s robust, interpretable, and economically valuable.

I’m keeping an open mind while holding firm on skepticism. That’s served me well in 25 years of quantitative finance. It will serve us well here too.


Author’s Assessment: Bull Case vs. Bear Case

The Bull Case: Kronos demonstrates that large-scale domain-specific pre-training on financial data extracts genuinely transferable knowledge. The zero-shot performance on unseen markets is real — a model that’s never seen a particular futures contract can still generate reasonable volatility forecasts. For new market entry, cross-asset correlation modelling, and synthetic scenario generation, this is genuinely valuable. The synthetic data capability alone could transform backtesting robustness, letting us stress-test strategies against crisis scenarios that occur once every 20 years without waiting for history to repeat.

The Bear Case: The paper benchmarks on MSE and CRPS — statistical metrics, not economic ones. A model that improves next-candle MSE by 5% may have an information coefficient of 0.01 — statistically detectable at 12 billion observations but worthless after bid-ask spreads. More fundamentally, training on 12 billion samples of approximately-IID noise teaches the model the shape of noise, not exploitable alpha. The pre-training captures volatility clustering (a risk characteristic), not conditional mean predictability (an alpha characteristic). GARCH does the former with two parameters and full transparency; Kronos does it with millions of parameters and a black box. Show me a backtest with realistic execution costs before calling this a trading signal.

The Bottom Line: Kronos is a promising research direction, not a production alpha engine. The most defensible near-term value is in synthetic data augmentation for stress testing — a workflow enhancement, not a signal source. Build institutional familiarity, run controlled pilots, but don’t deploy for live trading until someone demonstrates economically exploitable returns after costs. The foundation model paradigm is directionally correct; the empirical evidence for direct alpha generation remains unproven.

Hands-On: Kronos vs GARCH

Let’s test the sidebar’s claim directly. We’ll fit a GARCH(1,1) to the same futures data and compare its volatility forecast to what Chronos produces:

import yfinance as yf
import numpy as np
import matplotlib.pyplot as plt
from arch import arch_model
from chronos import ChronosPipeline

# Fetch data
data = yf.download("ES=F", period="1y", progress=False)
returns = data['Close'].pct_change().dropna() * 100

# Split: use 80% for fitting, 20% for testing
split = int(len(returns) * 0.8)
train, test = returns[:split], returns[split:]

# GARCH(1,1) forecast
garch = arch_model(train, vol='Garch', p=1, q=1, dist='normal')
garch_fit = garch.fit(disp='off')
garch_forecast = garch_fit.forecast(horizon=len(test)).variance.iloc[-1].values

# Chronos forecast
pipeline = ChronosPipeline.from_pretrained("amazon/chronos-t5-large", device_map="cuda")
chronos_preds = pipeline.predict(train.values, prediction_length=len(test))
chronos_forecast = np.std(chronos_preds, axis=0) # Volatility as std dev

# MSE comparison
garch_mse = np.mean((garch_forecast - test.values**2)**2)
chronos_mse = np.mean((chronos_forecast - test.values**2)**2)

print(f"GARCH MSE: {garch_mse:.4f}")
print(f"Chronos MSE: {chronos_mse:.4f}")

# Plot
fig, ax = plt.subplots(figsize=(10, 4))
ax.plot(test.index, test.values**2, label="Realized", color="black", alpha=0.7)
ax.plot(test.index, garch_forecast, label="GARCH", color="blue")
ax.plot(test.index, chronos_forecast, label="Chronos", color="orange")
ax.set_title("Volatility Forecast: GARCH vs Foundation Model")
ax.legend()
plt.tight_layout()
plt.show()

Volatility Forecast Comparison: GARCH(1,1) vs Chronos Foundation Model

Volatility Forecast Comparison: GARCH(1,1) vs Chronos Foundation Model

The bear case isn’t wrong: GARCH does volatility with 2 interpretable parameters and transparent assumptions. The foundation model uses millions of parameters. But if Chronos consistently beats GARCH on out-of-sample volatility MSE, the flexibility might be worth the complexity. Try running this yourself — the answer depends on the regime.