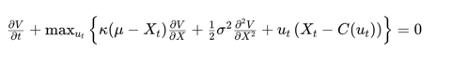
A Sharpe of 2.1 From Nothing: The Second Number Your Agent Doesn’t Log

September 2026

I gave a research agent four years of prices with no predictable structure in them — none, by construction — and it came back with a long/short book, an in-sample Sharpe of 2.1, and a paragraph explaining the economics of an effect that does not exist.

That is the measurement in this post. The more useful result is the second one: 88% of that number is accounted for by two integers — how many backtests the agent ran, and how many of the winners it blended into the book it reported. Only one of those is in the log everybody proposes to collect.

This closes a sequence. In August, having built an agentic research pipeline in May and measured a 2× lift in hypotheses tested per week, I priced a risk I had not thought to price: independent research runs against the same model produce books correlated at 0.62, a crowding exposure that appears in nobody’s risk report. That post ended with a claim I stated and did not measure — that faster hypothesis generation makes overfitting worse rather than better. This is the measurement, and my pre-registered prediction about how it would come out was wrong.


The one property agentic research has that human research never had

Every multiple-testing correction in finance founders on the same rock: you cannot observe the denominator. Harvey, Liu and Zhu built their t-statistic hurdle on an estimate of how many factors had been tried across the profession, not how many were published [1]. Harvey’s 2017 AFA presidential address is largely an argument about unreported trials [2]. The Deflated Sharpe Ratio requires you to supply the number of trials, and its authors are candid that in practice you are guessing [3]. Each method asks the researcher a question the researcher cannot honestly answer: how many things did you try before this one?

An agentic pipeline is different in exactly one respect. It has to ask the harness for every backtest it runs. The trial count is not a memory or an act of professional honesty. It is a log file.

So I built a minimal research agent, gave it one tool, recorded everything, and checked what the log is worth. The short answer is that it is worth less than I expected, for a reason that turns out to be measurable and fixable.


Setup

The harness. One command: submit up to 25 expressions, receive their in-sample scores. At most 12 such calls. The agent never sees prices, dates, tickers, or the holdout — the panel is anonymised to integer asset IDs and an integer time index, and the holdout files were physically absent from the filesystem while the runs executed. Every submission is logged with a timestamp, alongside a one-line hypothesis per batch and a free-text journal. The run ends when the agent reports exactly three signals.

What a “book” is, and the two counts that matter. Every arm’s output is scored the same way: three signals, equal-weighted into one book. The pre-registered primary rule takes the three highest-scoring signals a run evaluated, not the three it chose to report — the gap between the two is small and is itself reported below. N is the number of trials in the log. k is the number of additive legs in the resulting book: three for a searcher whose signals are single expressions, more for one whose signals are themselves sums. Those two integers carry the whole argument.

The signal language. A small price-only grammar: returns, moving averages, rolling moments, range position, rolling beta and correlation to the equal-weight panel, plus cross-sectional and time-series normalisations and arithmetic. It is the grammar from the August post, which matters — it was fixed before this hypothesis existed. Each signal becomes a dollar-neutral, rank-weighted long/short book with a one-day implementation lag.

The comparison arms. Three mechanical arms plus a no-selection placebo. The two that search run at the agent’s interaction schedule — 12 rounds of 25 candidates, feedback once per round. Matching rounds rather than evaluations is deliberate: in adaptive data analysis the damage scales with how many times you look and act, not with the raw query count [4].

ArmWhat it is
AGENTThe LLM researcher above
OPTEvolutionary search over the same grammar, at three selection pressures (soft, medium, hard — how aggressively each generation is bred from the current leaders)
CANON-SAMPLERCanon-shaped expressions with jittered parameters, no feedback — prior direction without optimisation
CANON placeboTwelve published anomalies in the same grammar, no selection at all

The data. The primary setting is synthetic: factor-structured panels with regime-switching volatility and fat tails, and zero predictability by construction. Volatility is forecastable; returns are not. The true Sharpe of every signal is zero, so every point of in-sample Sharpe is selection, and I can generate independent panels at will. The second setting is the real NASDAQ panel from the August post — 1,280 names, 2018–2023, train through 2021, holdout 2022 to May 2023.

The analysis plan, estimators, inclusion rule and predictions were committed to git before the first agent run. The repo holds the commit history, every harness log with its batch notes and research journals, a manifest of all 227 attempted runs including the five abandoned and why, and a list of every deviation from the plan.


1. What a research agent does with data that contains nothing

Twelve independent zero-alpha panels, one agent run each, identical prompt to the real-panel runs.

Every run found something. Every run wrote a confident rationale. From the report of a run on a panel whose returns are serially unpredictable by construction:

“All three combine the two independently validated engines: long-horizon cross-sectional mean reversion (ma 120-250, plateau confirmed across ret, ma, minr and maxr formulations at horizons 60-250) and a weekly return echo (returns from days t-8 to t-5 predict positively, with a coherent oscillating lag profile).”

There is no echo. There is no reversal. There is nothing.

Zero-alpha panelsReported in-sample SharpeRealised out-of-sample Sharpe
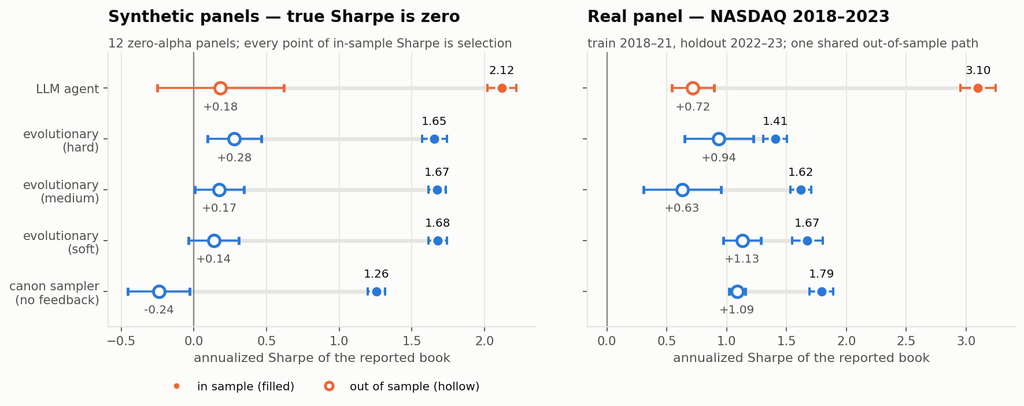
LLM agent (12 runs)2.12 (SE 0.10)+0.18 (SE 0.44)
Evolutionary, soft (12 panels)1.68 (SE 0.07)+0.14 (SE 0.24)
Evolutionary, medium1.67 (SE 0.05)+0.17 (SE 0.22)
Evolutionary, hard1.65 (SE 0.11)+0.28 (SE 0.22)
Canon sampler, no feedback1.26 (SE 0.08)−0.24 (SE 0.29)

The reported book is the equal-weight composite of the three highest-scoring signals a run evaluated — the pre-registered primary rule, which is why it differs slightly from what the agent chose to report. True out-of-sample Sharpe is zero for every arm by construction, and every row is consistent with that. Standard errors are across panels.

A Sharpe ratio of 2.12, in-sample, on a book, over four years of daily data, from a panel with no signal in it.

A little over half of that is textbook. The expected maximum Sharpe of a single expression over the agent’s own median 146 logged trials is 1.15 (SE 0.03, across the twelve panels’ random-expression pools) — the expected-maximum-Sharpe effect [3], computed here as the exact order statistic over an empirical null pool drawn from the same grammar. That accounts for 54% of the 2.12. Note what the benchmark cannot do: those are single expressions, and it takes a single expression as the answer. Hold that thought — the missing 0.97 is the subject of section 3.

The agent’s own judgment is not the problem. It usually declines to report its top three by raw score, preferring what it calls “plateau” specifications; that restraint moves the number by 0.03 (2.08 chosen versus 2.12 argmax).
In-sample versus out-of-sample by search arm

2. It manufactures more than a machine built to overfit

Paired by panel, against the evolutionary optimiser at the identical interaction schedule, using only the twelve primary runs:

Contrast, in-sample Sharpe (12 paired panels)DifferenceSEt
Agent − evolutionary (soft)+0.440.11+3.9
Agent − evolutionary (medium)+0.450.11+4.1
Agent − evolutionary (hard)+0.460.09+5.2

On the real panel the gap is larger: 3.10 against 1.41–1.67.

That is the in-sample difference, and it is solid. The out-of-sample differences are not: those contrasts carry standard errors of 0.35 to 0.42, against a minimum detectable effect of about 1.0 Sharpe, and the pre-registered block bootstrap on the real panel returns a 95% interval of [−0.53, +1.99] for the agent’s realised Sharpe alone. Nothing in this study establishes that the agent’s books perform worse out of sample than a mechanical optimiser’s. What it establishes is that at a matched interaction budget, the agent converts noise into reported Sharpe more efficiently.

My pre-registered prediction was the opposite — that the model’s priors would act as a regulariser, keeping it in the published canon rather than in the noise, so it would overfit less. Wrong, at t ≈ 4.

3. Where the extra Sharpe comes from is not more searching

The mechanism is in the logs, and it is not model priors.

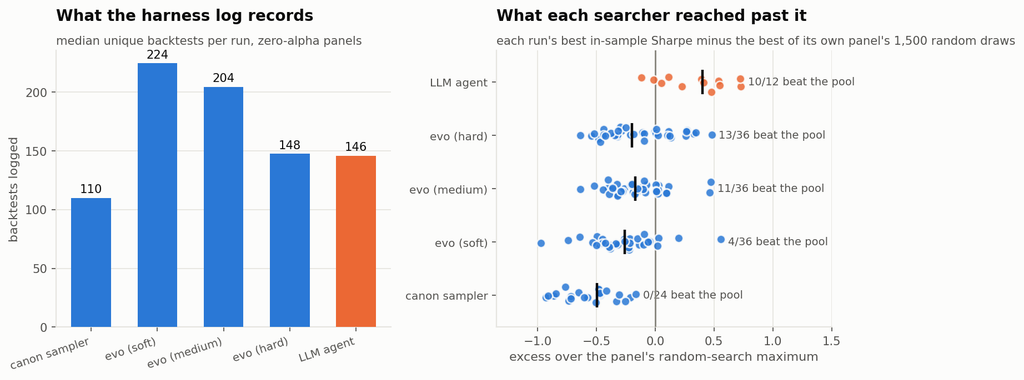
The agent logs a median of 146 unique backtests per zero-alpha run, against 148–225 for the evolutionary arms: level with the hardest setting, well below the softer ones. It is not searching harder — and note that the largest gap in the table above, +0.46, is against the arm that runs the same number of trials.

The difference is in what gets reported. Every run reports three signals, which are equal-weighted into one book. For the mechanical arms each of those three is a single expression, so the book has 3 legs. The agent’s three are themselves sums: a median of 4.2 legs each on zero-alpha panels, so its book carries about 12.5. That is the second integer, and no trial-count correction records it.

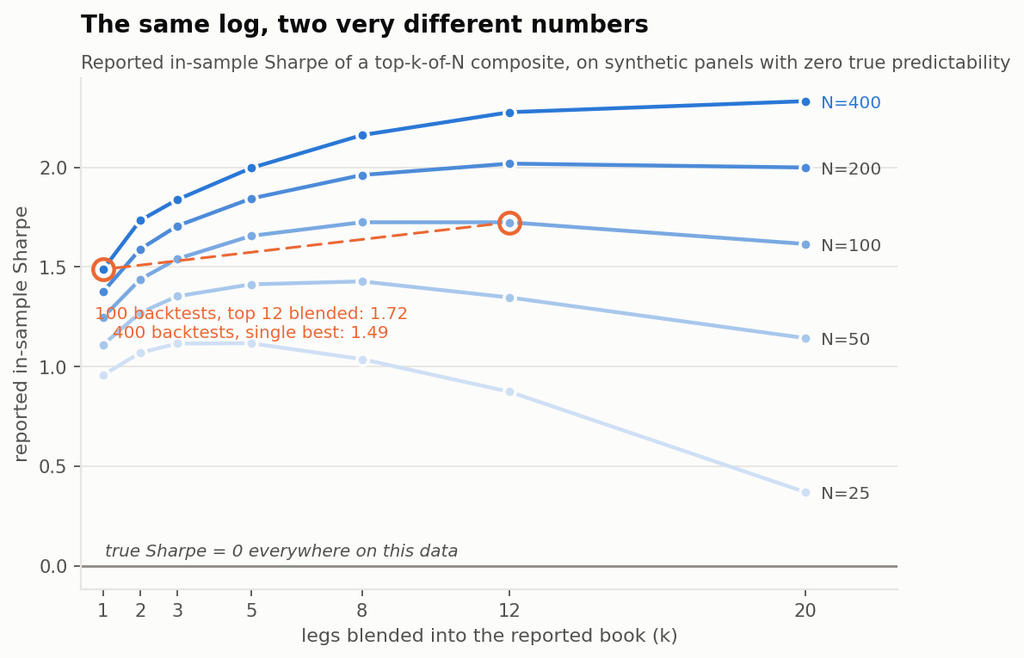
To isolate it I ran a controlled experiment on the zero-alpha panels with no agent involved: draw N random expressions, keep the top k by in-sample Sharpe, equal-weight them into a book, and record what the book reports.
The selection-plus-aggregation surface

Moving between curves is the familiar overfitting-versus-trials axis. Moving right along a curve is the aggregation axis nobody logs. The two trade off against each other: a pipeline that logs 100 backtests and blends its top 12 reports 1.72, while one that logs 400 and reports a single best reports 1.49. No alpha in either case, and the first pipeline’s log looks four times cleaner.

The arithmetic is standard portfolio algebra pointed at noise. Selecting k signals on in-sample performance and averaging them keeps the selected mean and cuts the variance — but the legs are not independent, so the gain is √(k / (1 + (k−1)ρ̄)), not √k. Fitting that form column by column over the monotone region gives ρ̄ of 0.41–0.47 at the trial counts that matter here, a ceiling of about 1.5× however many legs you add. That is why the curves flatten. They turn down at small N for a different reason: once k is a large fraction of N you are averaging in candidates that were barely selected at all. Novy-Marx made the combination point for strategies built from multiple signals and derived corrected critical values for it [5]; what is new here is an agent that was never asked to combine anything doing it unprompted, and the interchangeability of the two axes at a fixed log.

The closure. Take each run’s own logged trial count and its own book leg count, look up what blind top-k-of-N selection produces at that point on the surface, and compare:

ArmMedian trialsLegs in bookBlind top-k-of-N predictsActually reportedResidual
LLM agent14612.51.862.12+0.26
Evolutionary, hard14831.681.65−0.03
Evolutionary, medium20531.731.67−0.05
Evolutionary, soft22531.771.68−0.09
Canon sampler11031.561.26−0.31

Two integers and no model price the evolutionary arms to within 0.09, and account for 88% of the agent’s number. The residual is +0.26 (t ≈ 2.1 once the surface’s own estimation error is propagated) — small next to the 1.86 that blind selection explains. And the leg axis alone carries most of the agent’s edge over the mechanical searchers: holding trials at the agent’s own 146 and moving the book from 3 legs to 12.5 adds +0.25, against a measured agent-minus-mechanical gap of +0.45.

So the agent beats the optimiser and is beaten by blind selection at its own operating point, and both facts have one cause. It blends; they do not.

That also settles what happened to the estimator I pre-registered. I had planned to report an effective trial count — the random draws from this grammar needed to match a run’s best score. It cannot be computed for most agent runs: 10 of 12 exceed the best their own panel’s 1,500-draw random pool reached, so no trial count reproduces them. That is partly a property of a finite pool and it is not agent-specific — 13 of 36 hard evolutionary runs also clear their pool — so nothing here rests on it. The direction is informative, though: a deeper random-expression pool (depth 6, mean complexity 5.9 against the shallow pool’s 3.6) lifts the 99th percentile from 0.95 to 1.24 and the maximum to 1.79 without closing the gap, because random expressions almost never build composites — mean legs 1.15.

Depth is not the axis. Blending is.
What the log records versus what random search reaches

4. The real panel

Six agent runs on the NASDAQ panel, trained through 2021, scored on 2022 to May 2023.

Real panelTrainHoldoutLegs in bookDaily turnover
LLM agent (6)3.10 (SE 0.15)+0.72 (SE 0.18)6.00.24
Canon sampler (5)1.79 (SE 0.10)+1.09 (SE 0.07)30.45
Evolutionary, soft (5)1.67 (SE 0.13)+1.13 (SE 0.16)30.43
Evolutionary, medium (5)1.62 (SE 0.09)+0.63 (SE 0.32)30.26
Evolutionary, hard (5)1.41 (SE 0.10)+0.94 (SE 0.29)30.49
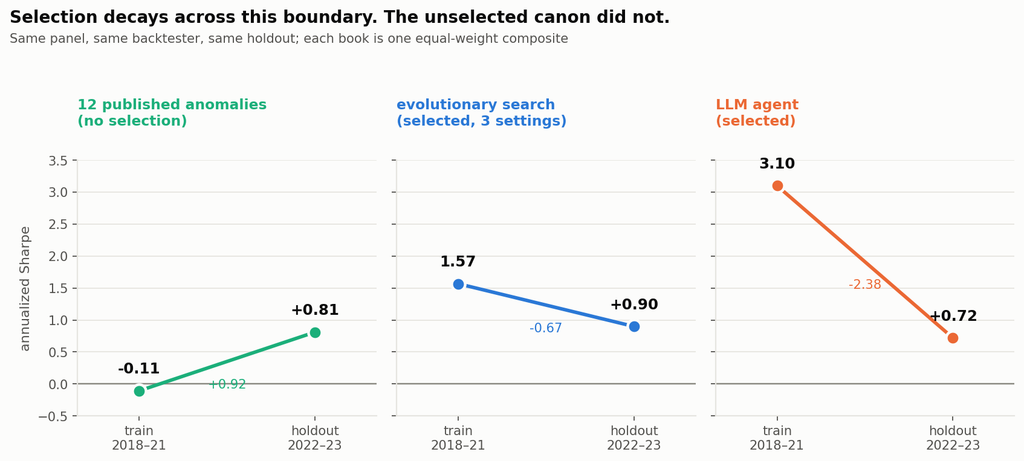
12 published anomalies, no selection−0.11+0.810.14

The last row is the control that makes the rest interpretable, and it is scored exactly like every other row — one equal-weight composite, same backtester, same holdout — with no selection applied. It does not decay across this boundary. It improves, from −0.11 to +0.81. The 2022–23 environment was kinder to these exposures on this universe than the training window was.

So the regime component of the agent’s decay is not merely small; it is negative. The control licenses one claim and not a stronger one: the unselected canon did not decay here, so the regime cannot explain the agent’s 2.4-point gap. It does not follow that selection explains all of it — the canon composite is loaded the opposite way from a book selected to score 3.10 in the training window, and the pre-registered random-search leg that would have measured the selection component directly was not run.

Note what the ordering does not do. It is not monotone — the medium evolutionary arm has the lowest holdout Sharpe of any arm, below the agent’s — and every one of those holdout differences sits inside the block-bootstrap intervals. The real panel cannot adjudicate between these arms.

Turnover does not explain the gap either: the agent’s books turn over 24% of gross per day, at the low end of the arms rather than the high end.
The unselected canon did not decay across this boundary

5. What the number is worth, and what it is not

The obvious next move is to use the zero-alpha number as a correction: subtract what the pipeline manufactures from noise off the face value of what it reports on real data. Since true Sharpe on the synthetic panels is zero by construction, the manufactured component is the reported in-sample Sharpe itself — 2.12 for the agent. That gives 3.10 − 2.12 = 0.98 predicted against 0.72 realised, which looks like a hit.

It is not. Run the same arithmetic for every arm:

ArmZero-alpha manufactureReal facePredictedRealisedPredicted − realised
LLM agent2.123.100.980.72+0.26
Evolutionary, soft1.681.67−0.001.13−1.13
Evolutionary, medium1.671.62−0.050.63−0.68
Evolutionary, hard1.651.41−0.250.94−1.18
Canon sampler1.261.790.541.09−0.55

A negative last column means the haircut left too little on the table. Mean error −0.66. The correction under-predicts realised performance in four arms out of five, and the agent’s near-miss is the one that landed the other way. These are five books on one shared holdout path, not five independent draws, so this is one observation with five views of it rather than five tests. The reason is in the previous table: this holdout carried a tailwind of roughly +0.9 for canonical exposures, which a calibration built on noise cannot know about.

So the zero-alpha number measures how much in-sample Sharpe your pipeline manufactures from nothing. It is not a forecast of out-of-sample performance, because realised performance also contains whatever the regime does to your exposures, and that term is not small. What it is worth is the overstatement:

Selection overstatement — $100M book at 10% target volatility
Face in-sample Sharpe of the reported book3.1
Measured manufacturing capacity (zero-alpha calibration)2.1
Annual return overstatement≈ $21M
In basis points of notional≈ 2,100 bp

The amount by which the in-sample report overstates, measured on data containing no alpha. Gross of costs, rounded. Not a forecast and not strategy P&L: the row above shows the haircut does not predict realised returns. Absolute performance levels on a survivorship-conditioned panel are not defensible and no such claim is made.


Things that did not work

Two pre-registered predictions failed. The first, above: the prior did not act as a regulariser. The second concerned the planted-alpha panels, where I buried two effects of equal calibrated in-sample strength — one canon-shaped (short-horizon reversal), one deliberately anti-canon (a kurtosis effect the literature points away from) — expecting the agent to find the canon-shaped one better and the mechanical arms to show no such asymmetry. Both halves were wrong. At the higher plant strength the agent captured the anti-canon plant better (0.50 versus 0.41), and it was the evolutionary arm that showed the large asymmetry (0.87 versus −0.02) and delivered more of the real alpha out of sample (1.15 versus 0.50). The comparison is confounded — the plants were matched on in-sample strength, but their oracle holdout Sharpes came out at 0.46 and 1.30 — and the agent contributes four runs per cell.

A metric that dissolved against its null — for the second post running. Regressing the agent’s real-panel books on the twelve-anomaly basis gives a mean R² of 0.50: the agent is largely reproducing published anomalies. Run the same regression on random expressions from the same grammar and you get 0.72. Noise projects onto the canon basis better than the agent’s books do — so the metric ranks the agent as less canonical than random noise, which is not a statement about the agent at all. It measures the dimensionality of price-signal space. The lesson is cheap and general: any spanning statistic needs a null drawn from the same generator, or it is measuring the basis.

The look-ahead screen cannot fire. The holdout sits inside the model’s training corpus, so I pre-registered a one-sided screen against block-bootstrap continuations of the training panel — futures the model cannot have seen. Resampling training returns reproduces the structure the books were selected on, so the synthetic benchmark runs at 1.5–2.0 Sharpe for selected books and the statistic is negative by construction (Δ = −0.92; −1.64 under the demeaned variant). It found no evidence of pretraining leakage; it also could not have. The construction is in the repo.

The model changed underneath the experiment. Two-thirds of the way through, a rate limit forced a checkpoint switch. Four partly-completed runs were abandoned under the pre-registered inclusion rule and re-run on the same four panels; a fifth run was abandoned after I contaminated it with an operator timing probe. All five are in the manifest. The twelve primary zero-alpha runs are all on the first checkpoint. Three bridge runs on the second checkpoint over the same panels reported 2.74 against 2.09 for the first checkpoint on those panels. That gap is not identified, by this post’s own mechanism: the bridge runs used their full 300-trial budget against the primary runs’ ~145, and at fixed leg count the surface predicts about half of the 0.65 gap from trials alone. Three runs is an anecdote in any case; it is reported because it is the clearest available evidence that these numbers are a snapshot of specific checkpoints. Which checkpoint served each run was never recorded — it is reconstructed from run identifiers and timing, which is a defect in my instrumentation and is flagged in the repo.


What this does and does not show

It does not show that agent-generated books underperform mechanically-generated ones out of sample. Those contrasts are inside their standard errors and the design cannot resolve them.

It does not show that a zero-alpha haircut predicts realised performance. Section 5 shows it does not.

The limitations that matter, in order. This is a minimal single-loop researcher — one agent, one tool, ≤300 trials, no holdout gate, no research committee — one to two orders below a production pipeline, and everything a real stack adds either raises the trial count or is a control whose value this same instrumentation would demonstrate. It is a floor. One model family, and a checkpoint that changed mid-study; the cross-family experiment could not be run. The real panel is one shared out-of-sample path on a survivorship-conditioned universe inside the model’s training corpus, so every real-panel number here is descriptive and the inference lives in the synthetic arm. Twelve panels is a small cross-section and every interval is wide. And the mechanical arms are matched on rounds and grammar but not perfectly: the evolutionary arm is seeded and mutated at bounded expression depth while the agent writes free-form strings, so the agent searches a strictly larger subspace — which is consistent with the finding, since composite depth is exactly the axis that matters, but it means “same grammar” is doing less work than it sounds like.

Eleven deviations from the pre-registration — the censored trial-count estimator, the random-search decomposition leg that was not run, 60 continuations instead of 200, the warm-start evaluation basis, a prompt revised after the plan was committed, and the rest — are listed in DEVIATIONS.md.


So what do you do

Build the surface for your own stack. This is the differentiated move and it costs almost nothing. Construct a panel matched to your universe — same factor covariance, same volatility dynamics, same fat tails — with the conditional mean stripped out, and verify the construction by checking that an oracle signal earns zero. Then run your own pipeline against it, unmodified, and record what it reports at each (trials, legs) pair you actually operate at. That grid is your pipeline’s manufacturing capacity in the units you use, and you can look up any future result on it. For the pipeline here it was 2.1 Sharpe. The generator and the surface code are in the repo and the whole thing runs on a laptop.

Log two numbers, not one. The trial count is now an artifact rather than a memory, and a pipeline that cannot produce one is worse off than this toy. But on its own it prices nothing: a 12-leg book from 100 trials carries more selection than a single expression from 400, and only the first of those facts is in the log everyone proposes to keep. With both numbers you can look the answer up on your own surface. With one you cannot.

Then subtract, and stop there. The result tells you how much of the reported number is manufacturing. It does not tell you what the book will earn, because that also depends on what the regime does to your exposures — and section 5 shows that term is larger than the correction.

Every zero-alpha run in this study produced a good economic story — volatility term structure, lottery preference, reversal at horizons where reversal is documented — attached to nothing. The pipeline is a fine instrument. It is also, on data containing nothing, a machine for producing a Sharpe of 2.1 and a paragraph about why.


Code and data

Repo: jkinlay/agent-selection-surface

The repository contains the pre-registered analysis plan committed before the first run, a deviations list, the frozen prompt, the harness, the mechanical arms, the synthetic generator with its calibration constants, every run log with its batch notes and research journals, the manifest of all 227 attempted runs with dispositions and reasons, the backtester canary tests, and the analysis and figure code. Everything downstream of the LLM calls reproduces from seeds; the LLM calls are not re-runnable, which is why the logs are included in full.

Two requests of anyone re-running it. Run the zero-alpha arm first — it is what makes every subsequent number interpretable. And log the leg count, not just the trial count.


References

[1] Harvey, Liu & Zhu, …and the Cross-Section of Expected Returns, Review of Financial Studies 29(1), 2016.

[2] Harvey, Presidential Address: The Scientific Outlook in Financial Economics, Journal of Finance 72(4), 2017.

[3] Bailey & López de Prado, The Deflated Sharpe Ratio, Journal of Portfolio Management 40(5), 2014; Bailey, Borwein, López de Prado & Zhu, Pseudo-Mathematics and Financial Charlatanism, Notices of the AMS 61(5), 2014, for the expected-maximum-Sharpe result used in section 1.

[4] Dwork, Feldman, Hardt, Pitassi, Reingold & Roth, The reusable holdout: Preserving validity in adaptive data analysis, Science 349(6248), 2015 — guarantees degrade with the number of adaptive rounds, which is why every arm here is matched on rounds rather than evaluations.

[5] Novy-Marx, Backtesting Strategies Based on Multiple Signals, NBER Working Paper 21329, 2015 — in-sample test statistics inflate with the number of combined signals, with corrected critical values. The aggregation axis in section 3 is this effect, arrived at by an agent that was not asked to combine anything.

[6] skfolio, load_nasdaq_dataset — daily adjusted closes, 1,455 NASDAQ constituents, 2018-01-02 to 2023-05-31, documented by its authors as a stale dataset not intended for investment or commercial use. Filtered here to 1,280 names with median price ≥ $5; SHA-256 of the source file is in the analysis plan.

[7] Canonical anomalies in the placebo: Jegadeesh & Titman (1993) with the Carhart (1997) 12-1 construction; Jegadeesh (1990); Ang, Hodrick, Xing & Zhang (2006); George & Hwang (2004); Frazzini & Pedersen (2014); Boyer, Mitton & Vorkink (2010); Moskowitz, Ooi & Pedersen (2012); Novy-Marx (2012). The twelfth, a 60-minus-120-day momentum-acceleration variant, is a construction of my own.

Disclosure: I run systematic strategies. Nothing here is a recommendation, and no strategy discussed is one I trade. These are diagnostic quantities from a methodological experiment on a stale public dataset, not a track record.
Optimal Mean-Reversion Strategies

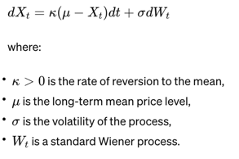
Consider a financial asset whose price, Xt​, follows a mean-reverting stochastic process. A common model for mean reversion is the Ornstein-Uhlenbeck (OU) process, defined by the stochastic differential equation (SDE):

The trader aims to maximize the expected cumulative profit from trading this asset over a finite horizon, subject to transaction costs. The trader’s control is the rate of buying or selling the asset, denoted by ut​, at time t.

To find the optimal trading strategy, we frame this as a stochastic control problem. The value function,V(t,Xt​), represents the maximum expected profit from time t to the end of the trading horizon, given the current price level Xt​. The HJB equation for this problem is:

where C(ut​) represents the cost of trading, which can depend on the rate of trading ut​. The term ut​(Xt​−C(ut​)) captures the profit from trading, adjusted for transaction costs.

Boundary and Terminal Conditions: Specify terminal conditions for V(T,XT​), where T is the end of the trading horizon, and boundary conditions for V(t,Xt​) based on the problem setup.

Solve the HJB Equation: The solution involves finding the function V(t,Xt​) and the control policy ut∗​ that maximizes the HJB equation. This typically requires numerical methods, especially for complex cost functions or when closed-form solutions are not feasible.

Interpret the Optimal Policy: The optimal control ut∗​ derived from solving the HJB equation indicates the optimal rate of trading (buying or selling) at any time t and price level Xt​, considering the mean-reverting nature of the price and the impact of transaction costs.

No-Trade Zones: The presence of transaction costs often leads to the creation of no-trade zones in the optimal policy, where the expected benefit from trading does not outweigh the costs.

Mean-Reversion Exploitation: The optimal strategy exploits mean reversion by adjusting the trading rate based on the deviation of the current price from the mean level, μ.

The Lipton & Lopez de Marcos Paper

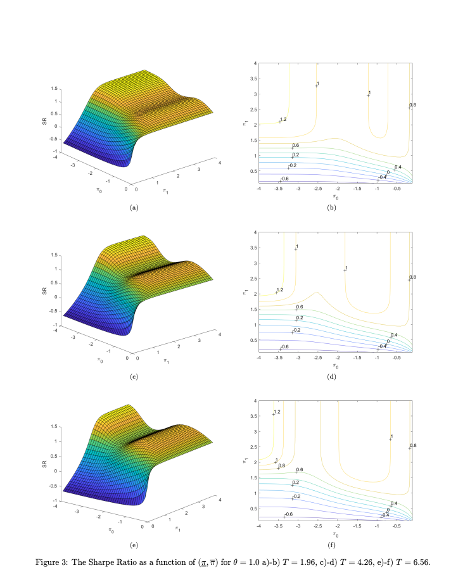
“A Closed-form Solution for Optimal Mean-reverting Trading Strategies” contributes significantly to the literature on optimal trading strategies for mean-reverting instruments. The paper focuses on deriving optimal trading strategies that maximize the Sharpe Ratio by solving the Hamilton-Jacobi-Bellman equation associated with the problem. It outlines a method that relies on solving a Fredholm integral equation to determine the optimal trading levels, taking into account transaction costs.

The paper begins by discussing the relevance of mean-reverting trading strategies across various markets, particularly emphasizing the energy market’s suitability for such strategies. It acknowledges the practical challenges and limitations of previous analytical results, mainly asymptotic and applicable to perpetual trading strategies, and highlights the novelty of addressing finite maturity strategies.

A key contribution of the paper is the development of an explicit formula for the Sharpe ratio in terms of stop-loss and take-profit levels, which allows traders to deploy tactical execution algorithms for optimal strategy performance under different market regimes. The methodology involves calibrating the Ornstein-Uhlenbeck process to market prices and optimizing the Sharpe ratio with respect to the defined levels. The authors present numerical results that illustrate the Sharpe ratio as a function of these levels for various parameters and discuss the implications of their findings for liquidity providers and statistical arbitrage traders.

The paper also reviews traditional approaches to similar problems, including the use of renewal theory and linear transaction costs, and compares these with its analytical framework. It concludes that its method provides a valuable tool for liquidity providers and traders to optimally execute their strategies, with practical applications beyond theoretical interest.

The authors use the path integral method to understand the behavior of their solutions, providing an alternative treatment to linear transaction costs that results in a determination of critical boundaries for trading. This approach is distinct in its use of direct solving methods for the Fredholm equation and adjusting the trading thresholds through a numerical method until a matching condition is met.

This research not only advances the understanding of optimal trading rules for mean-reverting strategies but also offers practical guidance for traders and liquidity providers in implementing these strategies effectively.

Money Management – the Good, the Bad and the Ugly

The infatuation of futures traders with the subject of money management, (more aptly described as position sizing), is something of a puzzle for someone coming from a background in equities or forex.  The idea is, simply, that one can improve one’s  trading performance through the judicious use of leverage, increasing the size of a position at times and reducing it at others.

MM Grapgic

Perhaps the most widely known money management technique is the Martingale, where the size of the trade is doubled after every loss.  It is easy to show mathematically that such a system must win eventually, provided that the bet size is unlimited.  It is also easy to show that, small as it may be, there is a non-zero probability of a long string of losing trades that would bankrupt the trader before he was able to recoup all his losses.  Still, the prospect offered by the Martingale strategy is an alluring one: the idea that, no matter what the underlying trading strategy, one can eventually be certain of winning.  And so a virtual cottage industry of money management techniques has evolved.

One of the reasons why the money management concept is prevalent in the futures industry compared to, say, equities or f/x, is simply the trading mechanics.  Doubling the size of a position in futures might mean trading an extra contract, or perhaps a ten-lot; doing the same in equities might mean scaling into and out of multiple positions comprising many thousands of shares.  The execution risk and cost of trying to implement a money management program in equities has historically made the  idea infeasible, although that is less true today, given the decline in commission rates and the arrival of smart execution algorithms.  Still, money management is a concept that originated in the futures industry and will forever be associated with it.

SSALGOTRADING AD

Van Tharp on Position Sizing
I was recently recommended to read Van Tharp’s Definitive Guide to Position Sizing, which devotes several hundred pages to the subject.  Leaving aside the great number of pages of simulation results, there is much to commend it.  Van Tharp does a pretty good job of demolishing highly speculative and very dangerous “money management” techniques such as the Kelly Criterion and Ralph Vince’s Optimal f, which make unrealistic assumptions of one kind or another, such as, for example, that there are only two outcomes, rather than the multiple possibilities from a trading strategy, or considering only the outcome of a single trade, rather than a succession of trades (whose outcome may not be independent).  Just as  with the Martingale, these techniques will often produce unacceptably large drawdowns.  In fact, as I have pointed out elsewhere, the use of leverage which many so-called money management techniques actually calls for increases in the risk in the original strategy, often reducing its risk-adjusted return.

As Van Tharp points out, mathematical literacy is not one of the strongest suits of futures traders in general and the money management strategy industry reflects that.

But Van Tharp  himself is not immune to misunderstanding mathematical concepts.  His central idea is that trading systems should be rated according to its System Quality Number, which he defines as:

SQN  = (Expectancy / standard deviation of R) * square root of Number of Trades

R is a central concept of Van Tharp’s methodology, which he defines as how much you will lose per unit of your investment.  So, for example, if you buy a stock today for $50 and plan to sell it if it reaches $40,  your R is $10.  In cases like this you have a clear definition of your R.  But what if you don’t?  Van Tharp sensibly recommends you use your average loss as an estimate of R.

Expectancy, as Van Tharp defines it, is just the expected profit per trade of the system expressed as a multiple of R.  So

SQN = ( (Average Profit per Trade / R) / standard deviation (Average Profit per Trade / R) * square root of Number of Trades

Squaring both sides of the equation, we get:

SQN^2  =  ( (Average Profit per Trade )^2 / R^2) / Variance (Average Profit per Trade / R) ) * Number of Trades

The R-squared terms cancel out, leaving the following:

SQN^2     =  ((Average Profit per Trade ) ^ 2 / Variance (Average Profit per Trade)) *  Number of Trades

Hence,

SQN = (Average Profit per Trade / Standard Deviation (Average Profit per Trade)) * square root of Number of Trades

There is another name by which this measure is more widely known in the investment community:  the Sharpe Ratio.

On the “Optimal” Position Sizing Strategy
In my view,  Van Tharp’s singular achievement has been to spawn a cottage industry out of restating a fact already widely known amongst investment professionals, i.e. that one should seek out strategies that maximize the Sharpe Ratio.

Not that seeking to maximize the Sharpe Ratio is a bad idea – far from it.  But then Van Tharp goes on to suggest that one should consider only strategies with a SQN of greater than 2, ideally much higher (he mentions SQNs of the order of 3-6).

But 95% or more of investable strategies have a Sharpe Ratio less than 2.  In fact, in the world of investment management a Sharpe Ratio of 1.5 is considered very good.  Barely a handful of funds have demonstrated an ability to maintain a Sharpe Ratio of greater than 2 over a sustained period (Jim Simon’s Renaissance Technologies being one of them).  Only in the world of high frequency trading do strategies typically attain the kind of Sharpe Ratio (or SQN) that Van Tharp advocates.  So while Van Tharp’s intentions are well meaning, his prescription is unrealistic, for the majority of investors.

One recommendation of Van Tharp’s that should be taken seriously is that there is no single “best” money management strategy that suits every investor.  Instead, position sizing should be evolved through simulation, taking into account each trader or investor’s preferences in terms of risk and return.  This makes complete sense: a trader looking to make 100% a year and willing to risk 50% of his capital is going to adopt a very different approach to money management, compared to an investor who will be satisfied with a 10% return, provided his risk of losing money is very low.  Again, however, there is nothing new here:  the problem of optimal allocation based on an investor’s aversion to risk has been thoroughly addressed in the literature for at least the last 50 years.

What about the Equity Curve Money Management strategy I discussed in a previous post?  Isn’t that a kind of Martingale?  Yes and no.  Indeed, the strategy does require us to increase the original investment after a period of loss. But it does so, not after a single losing trade, but after a series of losses from which the strategy is showing evidence of recovering.  Furthermore, the ECMM system caps the add-on investment at some specified level, rather than continuing to double the trade size after every loss, as in a Martingale.

But the critical difference between the ECMM and the standard Martingale lies in the assumptions about dependency in the returns of the underlying strategy. In the traditional Martingale, profits and losses are independent from one trade to the next.  By contrast, scenarios where ECMM is likely to prove effective are ones where there is dependency in the underlying strategy, more specifically, negative autocorrelation in returns over some horizon.  What that means is that periods of losses or lower returns tend to be followed by periods of gains, or higher returns.  In other words, ECMM works when the underlying strategy has a tendency towards mean reversion.

CONCLUSION
The futures industry has spawned a myriad of position sizing strategies.  Many are impractical, or positively dangerous, leading as they do to significant risk of catastrophic loss.  Generally, investors should seek out strategies with higher Sharpe Ratios, and use money management techniques only to improve the risk-adjusted return.  But there is no universal money management methodology that will suit every investor.  Instead, money management should be conditioned on each individual investors risk preferences.

Creating Robust, High-Performance Stock Portfolios

Summary

In this article, I am going to look at how stock portfolios should be constructed that best meet investment objectives.

The theoretical and practical difficulties of the widely adopted Modern Portfolio Theory approach limits its usefulness as a tool for portfolio construction.

MPT portfolios typically produce disappointing out-of-sample results, and will often underperform a naïve, equally-weighted stock portfolio.

The article introduces the concept of robust portfolio construction, which leads to portfolios that have more stable performance characteristics, including during periods of high volatility or market corrections.

The benefits of this approach include risk-adjusted returns that substantially exceed those of traditional portfolios, together with much lower drawdowns and correlations.

Market Timing

In an earlier article, I discussed how investors can enhance returns through the strategic use of market timing techniques to step out of the market during difficult conditions.

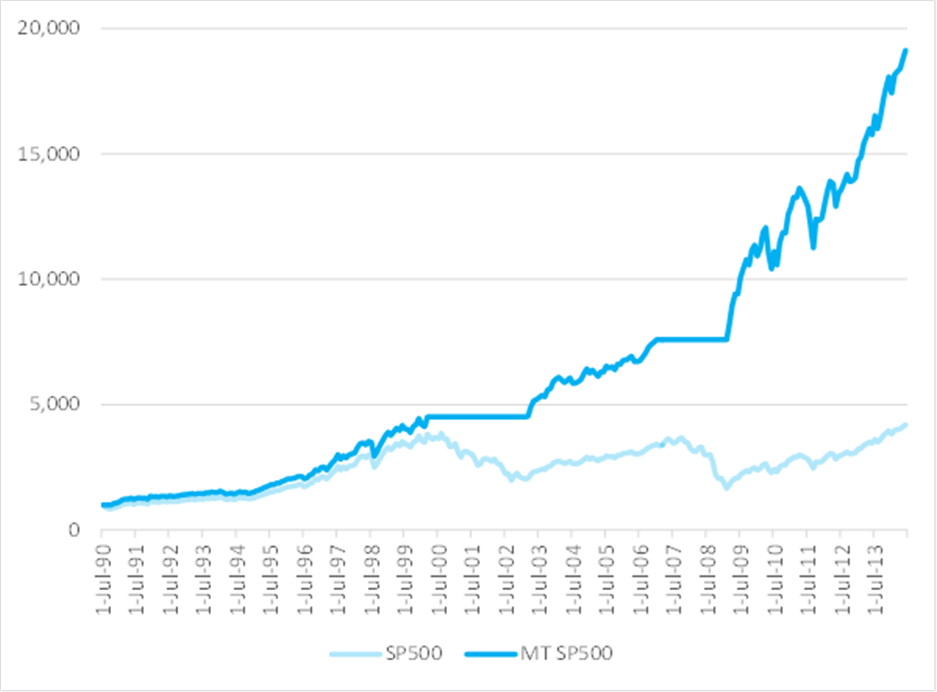
To emphasize the impact of market timing on investment returns, I have summarized in the chart below how a $1,000 investment would have grown over the 25-year period from July 1990 to June 2014. In the baseline scenario, we assume that the investment is made in a fund that tracks the S&P 500 Index and held for the full term. In the second scenario, we look at the outcome if the investor had stepped out of the market during the market downturns from March 2000 to Feb 2003 and from Jan 2007 to Feb 2009.

Fig. 1: Value of $1,000 Jul 1990-Jun 2014 – S&P 500 Index with and without Market Timing

Source: Yahoo Finance, 2014

After 25 years, the investment under the second scenario would have been worth approximately 5x as much as in the baseline scenario. Of course, perfect market timing is unlikely to be achievable. The best an investor can do is employ some kind of market timing indicator, such as the CBOE VIX index, as described in the previous article.

Equity Long Short

For those who mistrust the concept of market timing or who wish to remain invested in the market over the long term regardless of short-term market conditions, an alternative exists that bears consideration.

The equity long/short strategy, in which the investor buys certain stocks while shorting others, is a concept that reputedly originated with Alfred Jones in the 1940s. A long/short equity portfolio seeks to reduce overall market exposure, while profiting from stock gains in the long positions and price declines in the short positions. The idea is that the investor’s equity investments in the long positions are hedged to some degree against a general market decline by the offsetting short positions, from which the concept of a hedge fund is derived.

SSALGOTRADING AD

There are many variations on the long/short theme. Where the long and short positions are individually matched, the strategy is referred to as pairs trading. When the portfolio composition is structured in a way that the overall market exposure on the short side equates to that of the long side, leaving zero net market exposure, the strategy is typically referred to as market-neutral. Variations include dollar-neutral, where the dollar value of aggregate long and short positions is equalized, and beta-neutral, where the portfolio is structured in a way to yield a net zero overall market beta. But in the great majority of cases, such as, for example, in 130/30 strategies, there is a residual net long exposure to the market. Consequently, for the most part, long/short strategies are correlated with the overall market, but they will tend to outperform long-only strategies during market declines, while underperforming during strong market rallies.

Modern Portfolio Theory

Theories abound as to the best way to construct equity portfolios. The most commonly used approach is mean-variance optimization, a concept developed in the 1950s by Harry Markovitz (other more modern approaches include, for example, factor models or CVAR – conditional value at risk).

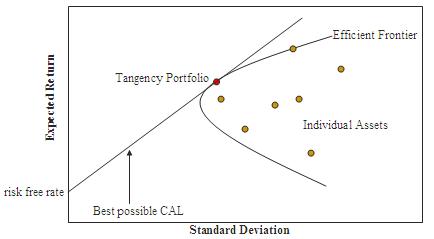
If we plot the risk and expected return of the assets under consideration, in what is referred to as the investment opportunity set, we see a characteristic “bullet” shape, the upper edge of which is called the efficient frontier (See Fig. 2). Assets on the efficient frontier produce the highest level of expected return for a given level of risk. Equivalently, a portfolio lying on the efficient frontier represents the combination offering the best possible expected return for a given risk level. It transpires that for efficient portfolios, the weights to be assigned to individual assets depend only on the volatilities of the individual assets and the correlation between them, and can be determined by simple linear programming. The inclusion of a riskless asset (such as US T-bills) allows us to construct the Capital Market Line, shown in the figure, which is tangent to the efficient frontier at the portfolio with the highest Sharpe Ratio, which is consequently referred to as the Tangency or Optimal Portfolio.

Fig. 2: Investment Opportunity Set and Efficient Frontier

Source: Wikipedia

Paradise Lost

Elegant as it is, MPT is open to challenge as a suitable basis for constructing investment portfolios. The Sharpe Ratio is often an inadequate representation of the investor’s utility function – for example, a strategy may have a high Sharpe Ratio but suffer from large drawdowns, behavior unlikely to be appealing to many investors. Of greater concern is the assumption of constant correlation between the assets in the investment universe. In fact, expected returns, volatilities and correlations fluctuate all the time, inducing changes in the shape of the efficient frontier and the composition of the optimal portfolio, which may be substantial. Not only is the composition of the optimal portfolio unstable, during times of financial crisis, all assets tend to become positively correlated and move down together. The supposed diversification benefit of MPT breaks down when it is needed the most.

I want to spend a little time on these critical issues before introducing a new methodology for portfolio construction. I will illustrate the procedure using a limited investment universe consisting of the dozen stocks listed below. This is, of course, a much more restricted universe than would typically apply in practice, but it does provide a span of different sectors and industries sufficient for our purpose.

Adobe Systems Inc. (NASDAQ:ADBE)
E. I. du Pont de Nemours and Company (NYSE:DD)
The Dow Chemical Company (NYSE:DOW)
Emerson Electric Co. (NYSE:EMR)
Honeywell International Inc. (NYSE:HON)
International Business Machines Corporation (NYSE:IBM)
McDonald’s Corp. (NYSE:MCD)
Oracle Corporation (NYSE:ORCL)
The Procter & Gamble Company (NYSE:PG)
Texas Instruments Inc. (NASDAQ:TXN)
Wells Fargo & Company (NYSE:WFC)
Williams Companies, Inc. (NYSE:WMB)

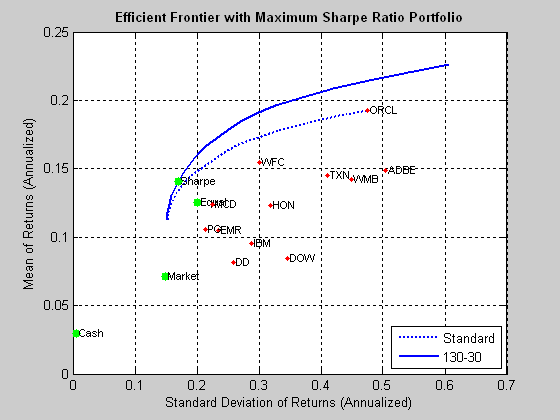
If we follow the procedure outlined in the preceding section, we arrive at the following depiction of the investment opportunity set and efficient frontier. Note that in the following, the S&P 500 index is used as a proxy for the market portfolio, while the equal portfolio designates a portfolio comprising identical dollar amounts invested in each stock.

Fig. 3: Investment Opportunity Set and Efficient Frontiers for the 12-Stock Portfolio

Source: MathWorks Inc.

As you can see, we have derived not one, but two, efficient frontiers. The first is the frontier for standard portfolios that are constrained to be long-only and without use of leverage. The second represents the frontier for 130/30 long-short portfolios, in which we permit leverage of 30%, so that long positions are overweight by a total of 30%, offset by a 30% short allocation. It turns out that in either case, the optimal portfolio yields an average annual return of around 13%, with annual volatility of around 17%, producing a Sharpe ratio of 0.75.

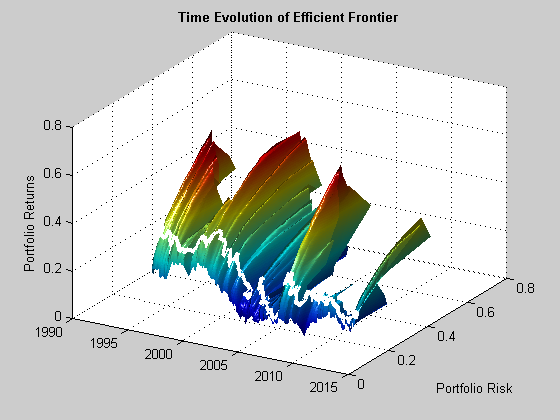
So far so good, but here, of course, we are estimating the optimal portfolio using the entire data set. In practice, we will need to estimate the optimal portfolio with available historical data and rebalance on a regular basis over time. Let’s assume that, starting in July 1995 and rolling forward month by month, we use the latest 60 months of available data to construct the efficient frontier and optimal portfolio.

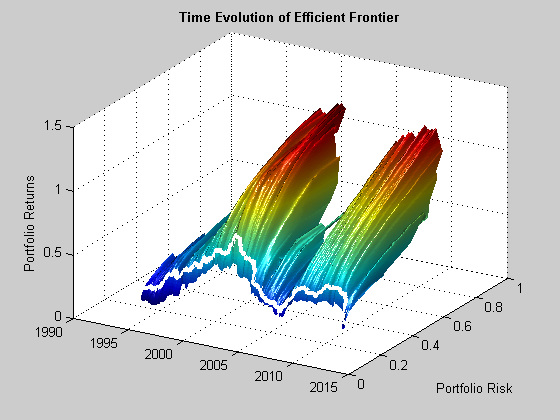
Fig. 4 below illustrates the enormous variation in the shape of the efficient frontier over time, and in the risk/return profile of the optimal long-only portfolio, shown as the white line traversing the frontier surface.

Fig. 4: Time Evolution of the Efficient Frontier and Optimal Portfolio

Source: MathWorks Inc.

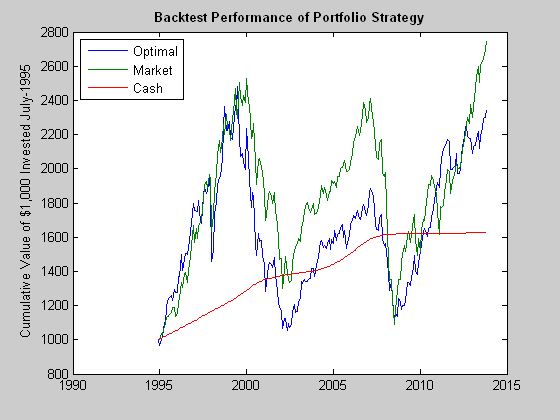
We see in Fig. 5 that the outcome of using the MPT approach is hardly very encouraging: the optimal long-only portfolio underperforms the market both in aggregate, over the entire back-test period, and consistently during the period from 2000-2011. The results for a 130/30 portfolio (not shown) are hardly an improvement, as the use of leverage, if anything, has a tendency to exacerbate portfolio turnover and other undesirable performance characteristics.

Fig. 5: Value of $1,000: Optimal Portfolio vs. S&P 500 Index, Jul 1995-Jun 2014

Source: MathWorks Inc.

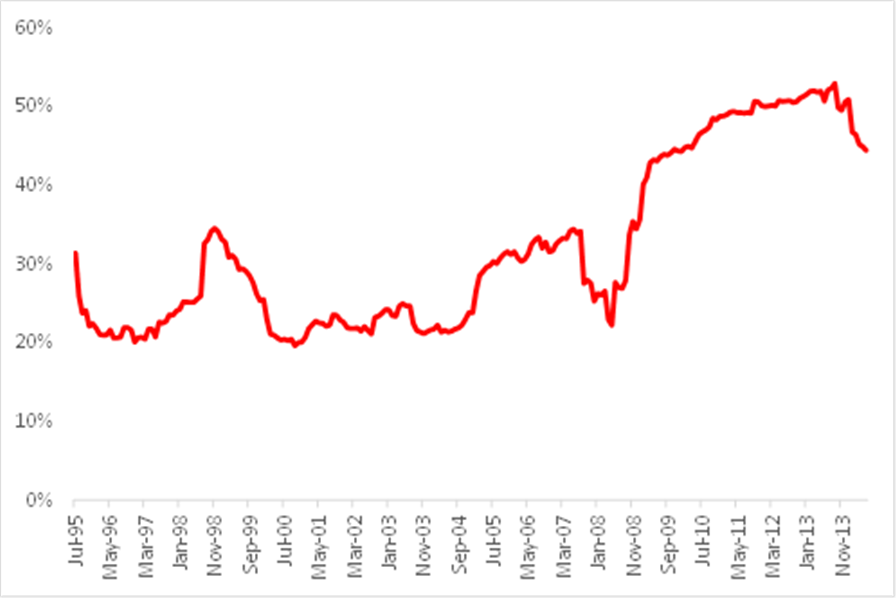
Part of the reason for the poor performance of the optimal portfolio lies with the assumption of constant correlation. In fact, as illustrated in Fig 6, the average correlation between the monthly returns in the twelve stocks in our universe has fluctuated very substantially over the last twenty years, ranging from a low of just over 20% to a high in excess of 50%, with an annual volatility of 38%. Clearly, the assumption of constant correlation is unsafe.

Fig. 6: Average Correlation, Jul 1995-Jun 2014

Source: Yahoo Finance, 2014

To add to the difficulties, researchers have found that the out of sample performance of the naïve portfolio, in which equal dollar value is invested in each stock, is typically no worse than that of portfolios constructed using techniques such as mean-variance optimization or factor models1. Due to the difficulty of accurately estimating asset correlations, it would require an estimation window of 3,000 months of historical data for a portfolio of only 25 assets to produce a mean-variance strategy that would outperform an equally-weighted portfolio!

Without piling on the agony with additional concerns about the MPT methodology, such as the assumption of Normality in asset returns, it is already clear that there are significant shortcomings to the approach.

Robust Portfolios

Many attempts have been made by its supporters to address the practical limitations of MPT, while other researchers have focused attention on alternative methodologies. In practice, however, it remains a challenge for any of the common techniques in use today to produce portfolios that will consistently outperform a naïve, equally-weighted portfolio. The approach discussed here represents a radical departure from standard methods, both in its objectives and in its methodology. I will discuss the general procedure without getting into all of the details, some of which are proprietary.

Let us revert for a moment to the initial discussion of market timing at the start of this article. We showed that if only we could time the market and step aside during major market declines, the outcome for the market portfolio would be a five-fold improvement in performance over the period from Aug 1990 to Jun 2014. In one sense, it would not take “much” to produce a substantial uplift in performance: what is needed is simply the ability to avoid the most extreme market drawdowns. We can identify this as a feature of what might be described as a “robust” portfolio, i.e. one with a limited tendency to participate in major market corrections. Focusing now on the general concept of “robustness”, what other characteristics might we want our ideal portfolio to have? We might consider, for example, some or all of the following:

  1. Ratio of total returns to max drawdown
  2. Percentage of profitable days
  3. Number of drawdowns and average length of drawdowns
  4. Sortino ratio
  5. Correlation to perfect equity curve
  6. Profit factor (ratio of gross profit to gross loss)
  7. Variability in average correlation

The list is by no means exhaustive or prescriptive. But these factors relate to a common theme, which we may characterize as robustness. A portfolio or strategy constructed with these criteria in mind is likely to have a very different composition and set of performance characteristics when compared to an optimal portfolio in the mean-variance sense. Furthermore, it is by no means the case that the robustness of such a portfolio must come at the expense of lower expected returns. As we have seen, a portfolio which only produces a zero return during major market declines has far higher overall returns than one that is correlated with the market. If the portfolio can be constructed in a way that will tend to produce positive returns during market downturns, so much the better. In other words, what we are describing is a long/short portfolio whose correlation to the market adapts to market conditions, having a tendency to become negative when markets are in decline and positive when they are rising.

The first insight of this approach, then, is that we use different criteria, often multi-dimensional, to define optimality. These criteria have a tendency to produce portfolios that behave robustly, performing well during market declines or periods of high volatility, as well as during market rallies.

The second insight from the robust portfolio approach arises from the observation that, ideally, we would want to see much greater consistency in the correlations between assets in the investment universe than is typically the case for stock portfolios. Now, stock correlations are what they are and fluctuate as they will – there is not much one can do about that, at least directly. One solution might be to include other assets, such as commodities, into the mix, in an attempt to reduce and stabilize average asset correlations. But not only is this often undesirable, it is unnecessary – one can, in fact, reduce average correlation levels, while remaining entirely with the equity universe.

The solution to this apparent paradox is simple, albeit entirely at odds with the MPT approach. Instead of creating our portfolio on the basis of combining a group of stocks in some weighting scheme, we are first going to develop investment strategies for each of the stocks individually, before combining them into a portfolio. The strategies for each stock are designed according to several of the criteria of robustness we identified earlier. When combined together, these individual strategies will merge to become a portfolio, with allocations to each stock, just as in any other weighting scheme. And as with any other portfolio, we can set limits on allocations, turnover, or leverage. In this case, however, the resulting portfolio will, like its constituent strategies, display many of the desired characteristics of robustness.

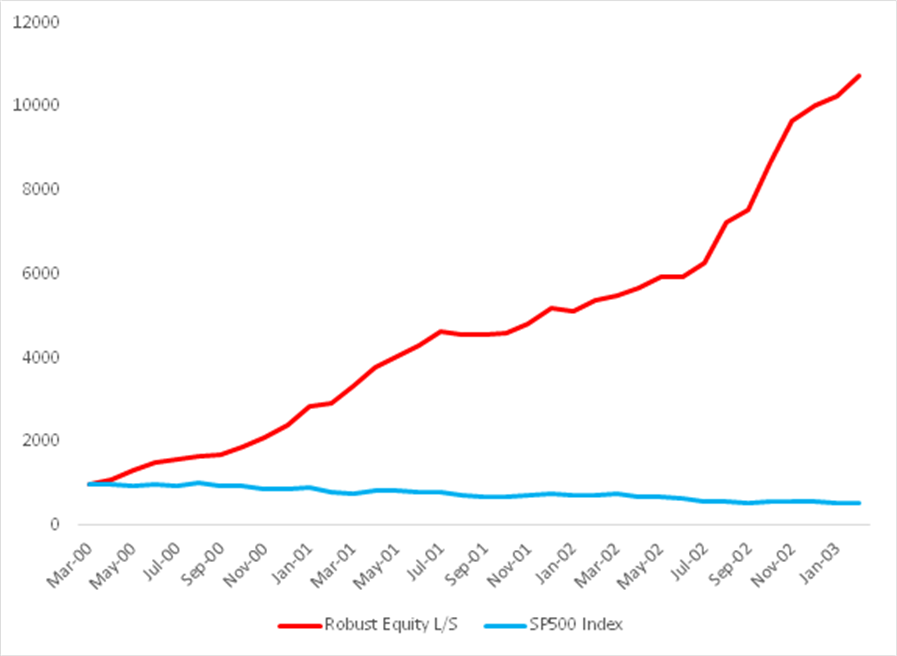
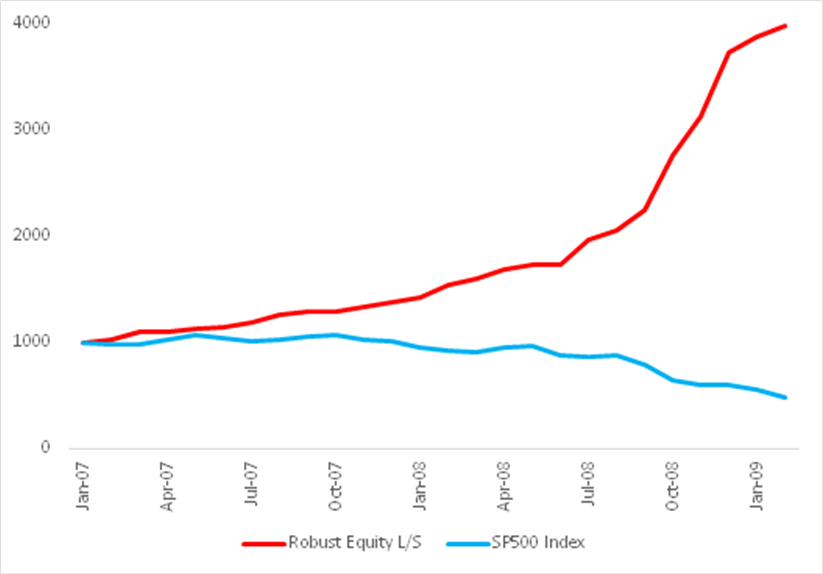
Let’s take a look at how this works out for our sample universe of twelve stocks. I will begin by focusing on the results from the two critical periods from March 2000 to Feb 2003 and from Jan 2007 to Feb 2009.

Fig. 7: Robust Equity Long/Short vs. S&P 500 index, Mar 2000-Feb 2003

Source: Yahoo Finance, 2014

Fig. 8: Robust Equity Long/Short vs. S&P 500 index, Jan 2007-Feb 2009

Source: Yahoo Finance, 2014

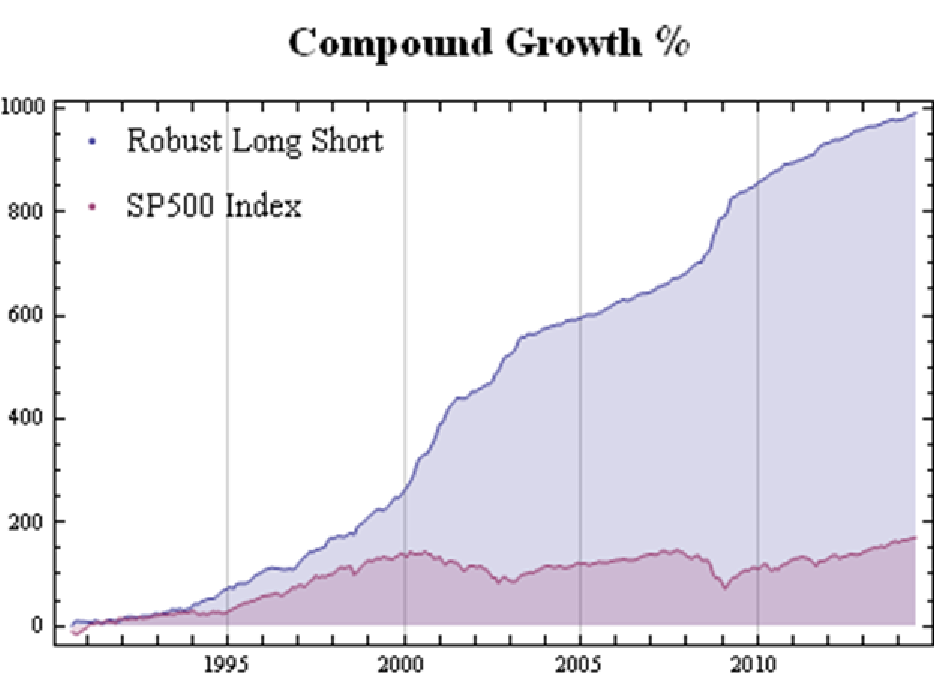
As might be imagined, given its performance during these critical periods, the overall performance of the robust portfolio dominates the market portfolio over the entire period from 1990:

Fig. 9: Robust Equity Long/Short vs. S&P 500 index, Aug 1990-Jun 2014

Source: Yahoo Finance, 2014

It is worth pointing out that even during benign market conditions, such as those prevailing from, say, the end of 2012, the robust portfolio outperforms the market portfolio on a risk-adjusted basis: while the returns are comparable for both, around 36% in total, the annual volatility of the robust portfolio is only 4.8%, compared to 8.4% for the S&P 500 index.

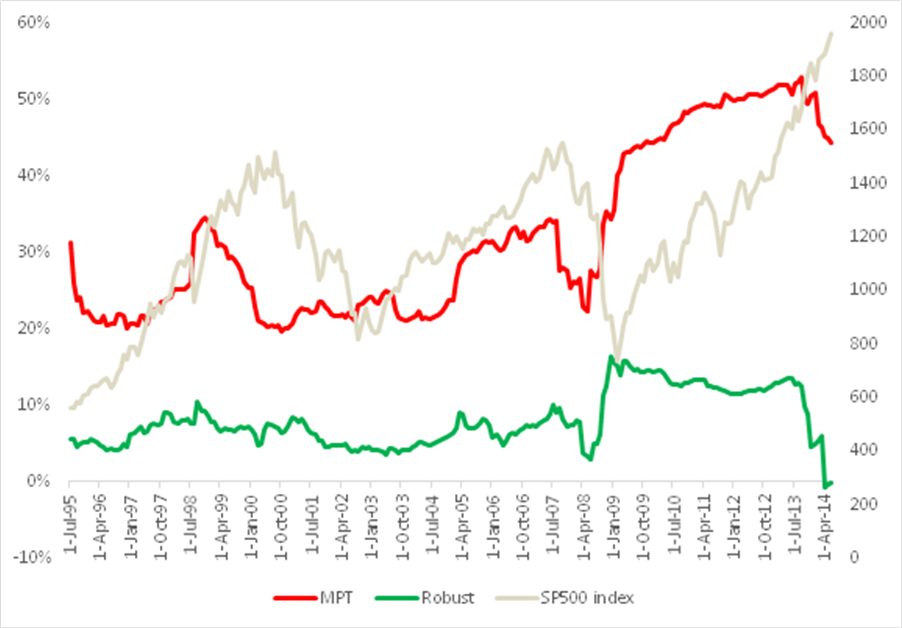
A significant benefit to the robust portfolio derives from the much lower and more stable average correlation between its constituent strategies, compared to the average correlation between the individual equities, which we considered before. As can be seen from Fig. 10, average correlation levels remained under 10% for the robust portfolio, compared to around 25% for the mean-variance optimal portfolio until 2008, rising only to a maximum value of around 15% in 2009. Thereafter, average correlation levels have drifted consistently in the downward direction, and are now very close to zero. Overall, average correlations are much more stable for the constituents in the robust portfolio than for those in the traditional portfolio: annual volatility at 12.2% is less than one-third of the annual volatility of the latter, 38.1%.

Fig. 10: Average Correlations Robust Equity Long/Short vs. S&P 500 index, Aug 1990-Jun 2014

Source: Yahoo Finance, 2014

The much lower average correlation levels mean that it is possible to construct fully diversified portfolios in the robust portfolio framework with fewer assets than in the traditional MPT framework. Put another way, a robust portfolio with a small number of assets will typically produce higher returns with lower volatility than a traditional, optimal portfolio (in the MPT sense) constructed using the same underlying assets.

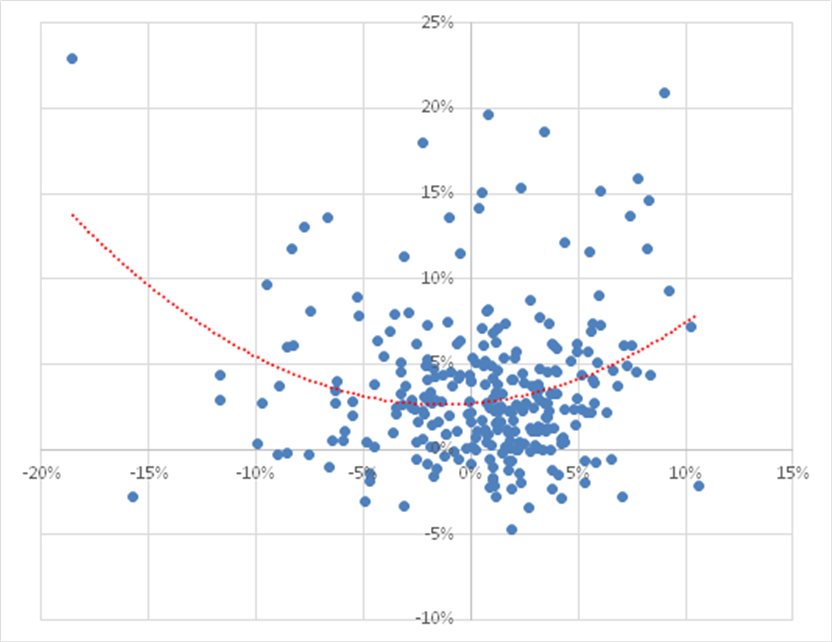
In terms of correlation of the portfolio itself, we find that over the period from Aug 1990 to June 2014, the robust portfolio exhibits close to zero net correlation with the market. However, the summary result disguises yet another important advantage of the robust portfolio. From the scatterplot shown in Fig. 11, we can see that, in fact, the robust portfolio has a tendency to adjust its correlation according to market conditions. When the market is moving positively, the robust portfolio tends to have a positive correlation, while during periods when the market is in decline, the robust portfolio tends to have a negative correlation.

Fig. 11: Correlation between Robust Equity Long/Short vs. S&P 500 index, Aug 1990-Jun 2014

Source: Yahoo Finance, 2014

Optimal Robust Portfolios

The robust portfolio referenced in our discussion hitherto is a naïve portfolio with equal dollar allocations to each individual equity strategy. What happens if we apply MPT to the equity strategy constituents and construct an “optimal” (in the mean-variance sense) robust portfolio?

The results from this procedure are summarized in Fig. 12, which shows the evolution of the efficient frontier, traversed by the risk/return path of the optimal robust portfolio. Both show considerable variability. In fact, however, both the frontier and optimal portfolio are far more stable than their equivalents for the traditional MPT strategy.

Fig. 12: Time Evolution of the Efficient Frontier and Optimal Robust Portfolio

Source: MathWorks Inc.

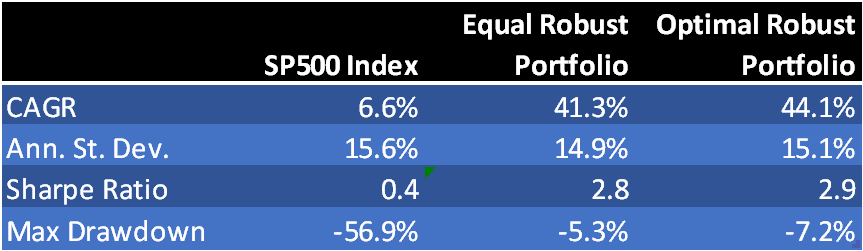
Fig. 13 compares the performance of the naïve robust portfolio and optimal robust portfolio. The optimal portfolio does demonstrate a small, material improvement in risk-adjusted returns, but at the cost of an increase in the maximum drawdown. It is an open question as to whether the modest improvement in performance is sufficient to justify the additional portfolio turnover and commensurate trading cost and operational risk. The incremental benefits are relatively minor, because the equally weighted portfolio is already well-diversified due to the low average correlation in its constituent strategies.

Fig. 13: Naïve vs. Optimal Robust Portfolio Performance Aug 1990-Jun 2014

Source: Yahoo Finance, 2014

Conclusion

The limitations of MPT in terms of its underlying assumptions and implementation challenges limits its usefulness as a practical tool for investors looking to construct equity portfolios that will enable them to achieve their investment objectives. Rather than seeking to optimize risk-adjusted returns in the traditional way, investors may be better served by identifying important characteristics of strategy robustness and using these to create strategies for individual equities that perform robustly across a wide range of market conditions. By constructing portfolios composed of such strategies, rather than using the underlying equities, investors may achieve higher, more stable returns under a broad range of market conditions, including periods of high volatility or market drawdown.

1 Optimal Versus Naive Diversification: How Inefficient is the 1/N Portfolio Strategy?, Victor DeMiguel, Lorenzo Garlappi and Raman Uppal, The Review of Financial Studies, Vol. 22, Issue 5, 2007.